AI Engineering
Articles on Python, machine learning, generative AI, AI agents, APIs, and deployment.
-
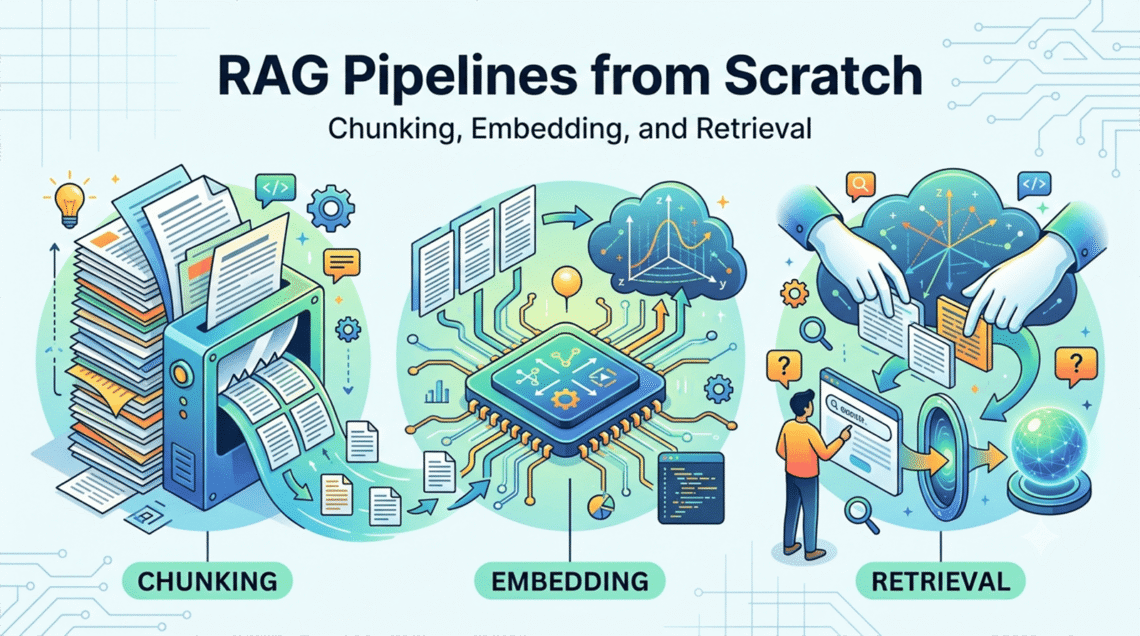
Complete RAG Pipelines from Scratch in 4 Steps: Chunking, Embedding, and Retrieval
The Problem RAG Solves
Do you want to learn how to build a RAG Pipeline from Scratch? Every large language model has a knowledge cutoff. It knows what it was trained on, and nothing beyond that. Ask a frontier model about a document it has never seen, a database record updated this morning, or a policy that changed last week, and it will either hallucinate an answer or tell you it does not know. For the vast majority of real enterprise AI applications, this is a fundamental limitation.
Retrieval-Augmented Generation (RAG) solves it. Rather than relying solely on what is baked into the model’s weights, RAG retrieves relevant content from an external knowledge source at query time and injects it into the model’s context window before generation. The model now has access to specific, current, verifiable information when it generates its answer. The result is a system that combines the reasoning capability of a frontier model with the factual grounding of a real knowledge base.
Building a RAG pipeline from scratch requires understanding three distinct stages: chunking the source documents into retrievable units, embedding those chunks into a vector space, and retrieving the right chunks at query time. Each stage has engineering decisions that significantly affect the quality of the final system.
Stage 1: Chunking
Chunking is the process of splitting source documents into smaller pieces that can be individually embedded and retrieved. It sounds simple, but it is where many RAG pipelines fail silently.
The core tension in chunking is between specificity and context. Small chunks are precise: a retrieval system can return exactly the passage relevant to a query without padding. But small chunks lose surrounding context, which means the model may receive a fragment that is accurate but uninterpretable without the sentences around it. Large chunks preserve context but dilute relevance: the retrieved passage contains the answer plus a lot of surrounding material that consumes precious context window tokens without contributing to the response.
Fixed-size chunking splits documents by token or character count, typically 256 to 512 tokens per chunk, with an overlap of 10 to 20 percent between adjacent chunks. The overlap ensures that sentences spanning a chunk boundary are represented fully in at least one chunk. This approach is fast, predictable, and easy to implement:
def fixed_size_chunks(text: str,
                      chunk_size: int = 512,
                      overlap: int = 64) -> list[str]:
    tokens = tokenizer.encode(text)
    chunks = []
    start = 0
    while start < len(tokens):
        end = min(start + chunk_size, len(tokens))
        chunks.append(tokenizer.decode(tokens[start:end]))
        start += chunk_size - overlap
    return chunks
Semantic chunking splits on natural boundaries: paragraphs, sections, or sentences, then merges adjacent units until a target size is reached. This preserves the logical structure of the document far better than fixed-size splitting and is the preferred approach for documents with clear section structure such as contracts, technical documentation, and research papers.
Hierarchical chunking maintains both a summary chunk and detailed sub-chunks for each section. At retrieval time, the system first retrieves summary-level chunks to identify the right section, then drills down to the detailed chunks within it. This approach produces significantly better results on long documents but requires more complex indexing infrastructure.
A practical rule: for structured documents such as PDFs, legal text, and technical manuals, use semantic chunking. For conversational logs, emails, and unstructured text, fixed-size chunking with generous overlap is typically sufficient. Always add metadata to each chunk: the source document name, page number, section heading, and creation date. This metadata is invaluable for filtering at retrieval time and for attributing sources in the final response.
Stage 2: Embedding
Once documents are chunked, each chunk must be converted into a dense vector that captures its semantic meaning. This is done using an embedding model: a neural network trained to map text into a high-dimensional space where semantically similar passages are geometrically close to each other.
The choice of embedding model matters significantly. The dominant options in 2026 are OpenAI’s
text-embedding-3-large(3,072 dimensions), Cohere’sembed-v3, and open-source alternatives such asbge-large-en-v1.5from BAAI ande5-mistral-7b-instructfrom Microsoft. Open-source models have the advantage of running locally, which matters for data-sensitive applications.Embedding a corpus in Python using the OpenAI API looks like this:
from openai import OpenAI
import numpy as np

client = OpenAI()

def embed_chunks(chunks: list[str],
                 model: str = "text-embedding-3-large") -> np.ndarray:
    response = client.embeddings.create(
        input=chunks,
        model=model
    )
    return np.array([item.embedding for item in response.data])
Two practical considerations deserve attention here. First, embed your queries using the same model you used to embed your documents. Mixing embedding models produces meaningless similarity scores because the vector spaces are incompatible. Second, normalise your embedding vectors before storing them if you plan to use cosine similarity for retrieval: most vector databases do this automatically, but it is worth verifying.
For domain-specific applications, fine-tuning an embedding model on in-domain data consistently outperforms general-purpose embeddings. A legal RAG system fine-tuned on case law retrieves significantly more relevant passages than a general embedding model applied to the same corpus, because the fine-tuned model learns the specific vocabulary and semantic relationships of the domain.
Stage 3: Vector Storage
Embeddings must be stored in a system that supports efficient similarity search. The options divide into three categories.
Dedicated vector databases such as Pinecone, Weaviate, Qdrant, and Milvus are purpose-built for high-dimensional vector search. They support filtering on metadata, approximate nearest-neighbour (ANN) search algorithms such as HNSW (Hierarchical Navigable Small World), and horizontal scaling to billions of vectors. For production systems with large corpora, these are the right choice.
Hybrid stores such as pgvector (a PostgreSQL extension) allow vector search within an existing relational database. This is useful when you want to combine semantic search with SQL filtering in a single query, which is a common pattern for structured data sources.
In-memory search using libraries such as FAISS or Annoy is suitable for development, prototyping, and small corpora where latency is critical and persistence is not required.
import faiss
import numpy as np

def build_faiss_index(embeddings: np.ndarray) -> faiss.IndexFlatIP:
    dimension = embeddings.shape[1]
    index = faiss.IndexFlatIP(dimension)  # inner product = cosine on normalised vectors
    faiss.normalize_L2(embeddings)
    index.add(embeddings)
    return index
Stage 4: Retrieval
At query time, the user’s question is embedded using the same model used to embed the documents, and the vector store is queried for the most similar chunks. This is where several common RAG pipeline failures occur, and where the most productive engineering improvements can be made.
Naive top-k retrieval returns the k most similar chunks by cosine similarity. It is a good starting point but has two well-known weaknesses. First, it relies entirely on the query embedding capturing the user’s intent accurately, which fails when queries are vague or use different terminology from the source documents. Second, the top-k chunks may all be from the same section of the same document, producing redundant context rather than diverse coverage.
Hybrid retrieval combines semantic (vector) search with keyword (BM25) search and merges the results using Reciprocal Rank Fusion (RRF). This is the most reliably effective retrieval strategy for general-purpose RAG and is now the default approach in most production systems. Keyword search catches exact term matches that semantic search misses; semantic search catches paraphrases and conceptual matches that keyword search misses.
Query rewriting passes the user’s query through the LLM before retrieval, expanding it into multiple alternative phrasings or decomposing a complex question into simpler sub-queries. Each sub-query is retrieved separately, and the results are merged before generation. This significantly improves retrieval quality on complex, multi-part questions.
Re-ranking adds a second-pass model after initial retrieval. A cross-encoder model such as Cohere Rerank or a locally hosted BGE re-ranker scores each retrieved chunk against the original query more accurately than the bi-encoder embedding similarity used in the initial retrieval, and re-orders the results accordingly. Re-ranking consistently improves answer quality at the cost of an additional model call.
Putting It Together
A minimal but complete RAG pipeline in production should: chunk documents semantically with metadata, embed with a domain-appropriate model, store in a vector database with metadata filtering, retrieve using hybrid search with re-ranking, and inject the retrieved context into a well-structured prompt with source attribution. Each of these steps is independently tunable, which means RAG pipeline quality can be improved incrementally without retraining the underlying LLM.
The engineering value of RAG is precisely this modularity. The knowledge base can be updated without touching the model. The retrieval strategy can be improved without reindexing. The generation model can be swapped without rebuilding the index. That separation of concerns is what makes RAG the most widely deployed pattern in production AI engineering today.
-
MCP vs API: Why Traditional APIs Are Failing AI Agents
The Integration Problem Nobody Anticipated
When developers began building the first generation of LLM-powered applications in 2023, the obvious approach was to reach for the tools already in the toolbox. REST APIs had connected software systems for two decades. They were well-understood, well-documented, and supported by mature tooling. The assumption was that connecting an AI agent to a database, a calendar, or a CRM would work just like connecting any other piece of software to those systems.
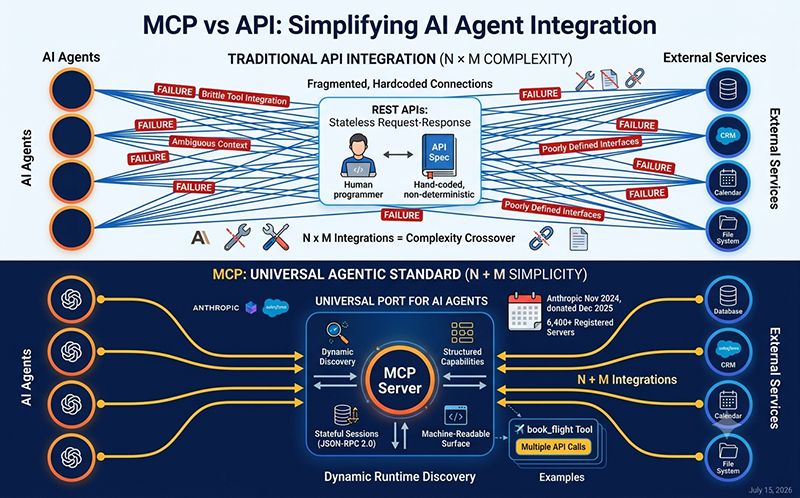
That assumption turned out to be wrong in ways that were not immediately obvious. Industry reports and Microsoft AI Red Team Research from 2025 show that agentic systems failed due to brittle tool integrations, ambiguous context handling, and poorly defined interfaces between models and the external world. The failures were not usually spectacular crashes. More often they were silent: agents producing subtly incorrect behaviour that took days to trace back to a broken integration. Understanding why requires looking at what REST APIs were actually designed for, and why that design is a poor match for how AI agents operate.
What REST APIs Were Built to Do
A REST API is a contract between a developer and a service. The developer writes code that calls a specific endpoint with specific parameters in a specific format, and the service returns a predictable response. The entire model is built around a human programmer who knows in advance what action needs to be taken, which endpoint handles it, and what the response structure means.
APIs let developers write deterministic code that calls specific endpoints. The distinction reshapes integration architecture for every team deploying AI in production. This is precisely the property that makes APIs unsuitable for agentic systems. An AI agent does not know in advance what actions it will need to take. It discovers the appropriate actions at runtime, based on its reasoning about the current state of a task. Asking an LLM to navigate a traditional REST API is like handing a new employee a 400-page API specification document and asking them to memorise it before making any decisions.
The second problem is statefulness. REST APIs use stateless HTTP. Each request carries its own authentication, parameters, and context. The server processes the request and forgets the caller. Stateless communication is excellent for web applications where millions of independent clients send independent requests. It is a poor fit for an agent executing a multi-step task over minutes or hours, where context from earlier steps needs to be maintained and referenced throughout.
The third problem is the integration explosion. Without a standardized protocol, each AI application must integrate directly with every external service, creating N times M separate integrations where N represents the number of tools and M represents the number of clients. This approach quickly becomes impossible to scale. An enterprise deploying five agents across ten internal tools would need fifty bespoke integrations, each hand-coded, each requiring its own maintenance, and each breaking independently when either the agent or the tool changes.
Enter MCP: The USB-C Port for AI
The Model Context Protocol (MCP) was introduced by Anthropic on November 25, 2024, and donated to the Linux Foundation’s Agentic AI Foundation (AAIF) in December 2025, co-governed by Anthropic, OpenAI, and Block as a vendor-neutral open standard. Think of MCP as a USB-C port for AI systems: just as USB-C standardises how devices connect to computers, MCP standardises how AI agents access external resources like databases, APIs, file systems, and knowledge bases.
The architectural difference from REST is fundamental. Rather than hardcoded connections to each external service, AI agents using MCP can dynamically discover available tools, understand their capabilities through structured calls, and invoke them with proper permissions. Instead of requiring the agent to know the endpoint, the parameter schema, and the response format for every possible tool call in advance, an MCP server exposes a machine-readable capability surface that the agent can query at runtime. The agent asks “what can you do?” before deciding what to do, which maps far more naturally onto how LLM reasoning actually works.
The session model is equally important. MCP maintains stateful JSON-RPC 2.0 sessions, whereas REST APIs are stateless request-response. A stateful session means the agent and the tool can maintain shared context across the entire duration of a multi-step task, with the server able to push progress updates and partial results directly into the agent’s reasoning loop rather than waiting for the agent to poll.
The N times M integration problem is solved structurally. MCP solves this by requiring each client and each server to implement the protocol just once, reducing total integrations from N times M to N plus M. Build one MCP server for your database, and every MCP-compatible agent can use it immediately, with no additional integration work on either side.
Tools, Not Endpoints: A Critical Distinction
One of the most important conceptual shifts MCP introduces is the distinction between a tool and an API endpoint. These sound similar but are architecturally different. Tools are not designed to be an abstraction over API calls but rather an abstraction over functionality. A tool may include multiple API calls in its implementation to achieve the desired outcome.
This distinction matters because it aligns with how agents reason. An agent does not want to know which HTTP endpoint to call. It wants to know what it can accomplish. A tool called
book_flightthat internally makes three API calls to a pricing service, an availability checker, and a booking system is far more useful to an agent than three separate REST endpoints that the agent must learn to orchestrate itself. The tool encapsulates the implementation; the agent sees only the capability.An agent will review the list of available tools to automatically select the most appropriate tools and determine the appropriate order of execution. This is exactly the kind of dynamic, context-driven decision-making that REST APIs, designed for deterministic developer-written code, cannot support natively.
Industry Adoption: The Tipping Point Has Passed
The signal that MCP had won the integration standard debate came in March 2025, when OpenAI officially adopted it. For years, OpenAI had cultivated its own walled garden via the Assistants API. However, the friction of maintaining proprietary integrations against a rapidly expanding open ecosystem became untenable. OpenAI’s adoption was accompanied by the announcement of the deprecation of the Assistants API, scheduled for sunset in mid-2026, compelling the entire developer ecosystem to migrate toward MCP-based architectures. Google followed with its own MCP support shortly after.
The growth of the ecosystem since then has been rapid. As of February 2026, the official MCP registry has over 6,400 MCP servers already registered. The November 2025 MCP specification update added critical enterprise capabilities: asynchronous operations so agents can initiate long-running tasks and retrieve results later, formal server identity verification, and structured audit trails. These additions directly addressed the governance concerns that slowed enterprise adoption through 2025.
Salesforce reported 4.5 million MCP calls processed through its Headless 360 platform within weeks of launch. The MCP Dev Summit North America in April 2026 drew approximately 1,200 attendees. The protocol is no longer experimental infrastructure; it is production reality at scale.
MCP Does Not Replace APIs. It Wraps Them.
A common misconception is that MCP makes REST APIs obsolete. The more accurate picture is that MCP does not replace APIs. It wraps them into a standardised layer that LLMs can navigate, turning the N times M integration problem into N plus M. The underlying services still expose REST endpoints. MCP sits in front of them as an intelligent, agent-friendly abstraction layer. Atlan
The practical decision rule is straightforward: use traditional APIs when a human developer is writing deterministic application code that calls a known endpoint. Use MCP when an AI agent needs to discover and invoke tools dynamically at runtime across multiple systems. For teams running three or more AI-connected integrations, the complexity crossover point where MCP reduces total integration cost is typically reached quickly.
What This Means for AI Engineers
For practitioners building agent systems today, MCP is no longer optional infrastructure to consider for future projects. It is the current standard. Every new data source requiring its own custom implementation makes truly connected systems difficult to scale. MCP addresses this challenge by providing a universal, open standard for connecting AI systems with data sources, replacing fragmented integrations with a single protocol. Anthropic
The engineering implication is direct: if you are building an AI agent that needs to connect to more than one external system, build or adopt MCP servers rather than hand-coding REST integrations. The ecosystem already contains over 6,400 servers covering databases, file systems, version control, CRMs, calendars, and hundreds of SaaS platforms. The connective tissue for the agentic web has been standardised. The remaining work is building the agents capable of using it well.
-
Building an AI Agent from Scratch: Tools, Memory, and Reasoning Loops
What Makes Something an Agent?
There is a meaningful difference between calling an LLM API and building an AI agent. A single API call takes an input, produces an output, and stops. An agent does something more: it perceives a situation, decides what action to take, executes that action, observes the result, and decides what to do next. That loop, repeated until the task is complete, is what makes something an agent rather than a wrapper.
The concept has deep roots in AI research, but the practical engineering of LLM-based agents has matured enormously in the past two years. Today, a competent Python developer can build a functional agent in an afternoon. Understanding what the agent is actually doing under the surface, and building it in a way that is reliable, observable, and safe, takes considerably more thought. This post walks through the three core components of any agent system: tools, memory, and the reasoning loop.
The Reasoning Loop: Think, Act, Observe, Repeat
The architectural heart of an LLM agent is the reasoning loop. The most widely used formulation is ReAct (Reasoning and Acting), introduced in a 2022 paper by Yao et al. at Princeton and Google Brain. The loop works as follows:
- The agent receives a task.
- It reasons about what to do next (Thought).
- It selects and calls a tool (Action).
- It receives the tool’s output (Observation).
- It reasons again, incorporating the observation.
- It repeats until it decides the task is complete and returns a final answer.
In code, this translates to a loop that sends the current state of the conversation to the LLM, parses its response for a tool call, executes the tool, appends the result to the conversation history, and calls the LLM again. A minimal Python implementation looks like this:
def run_agent(task: str, tools: dict, max_steps: int = 10) -> str:
    messages = [
        {"role": "system", "content": build_system_prompt(tools)},
        {"role": "user",   "content": task}
    ]

    for step in range(max_steps):
        response = call_llm(messages)
        action = parse_action(response)

        if action["type"] == "final_answer":
            return action["content"]

        observation = tools[action["name"]](**action["args"])

        messages.append({"role": "assistant", "content": response})
        messages.append({"role": "user",
                         "content": f"Observation: {observation}"})

    return "Max steps reached without a final answer."
Several things in this skeleton are worth noting. The
max_stepsguard is not optional: without it, a confused or looping agent will burn tokens indefinitely. The system prompt must describe the available tools clearly, including their names, what they do, and the exact format the model should use to call them. Andparse_actionneeds to be robust: LLMs do not always produce perfectly formatted output, so defensive parsing with fallback handling is essential in production.Tools: Giving the Agent Hands
A tool is any function the agent can call to interact with the world outside the LLM’s context window. Common tools in production agents include web search, code execution, file reading and writing, database queries, REST API calls, calculator functions, and retrieval from a vector store. The principle is simple: if the agent needs information or capabilities that are not already in its context, it needs a tool to get them.
Defining tools well is one of the most important engineering decisions in agent design. Each tool should do one thing clearly, return results in a consistent and parseable format, handle errors gracefully rather than crashing the loop, and be as fast as possible since every tool call adds latency. A poorly designed tool that returns noisy or ambiguous output will confuse the model, produce bad reasoning, and waste steps.
In the OpenAI API, tools are defined as JSON schemas that the model uses to structure its calls:
tools = [
    {
        "type": "function",
        "function": {
            "name": "web_search",
            "description": "Search the web for current information.",
            "parameters": {
                "type": "object",
                "properties": {
                    "query": {
                        "type": "string",
                        "description": "The search query."
                    }
                },
                "required": ["query"]
            }
        }
    }
]
The Anthropic API uses an equivalent structure. The key discipline is writing the
descriptionfield carefully: the model reads it to decide when and how to use the tool, so vague descriptions produce inconsistent tool selection.Memory: What the Agent Knows and Remembers
Memory in AI agents divides into four types, each serving a different purpose.
In-context memory is the simplest: everything in the current conversation history that the model can see. It is immediate and requires no infrastructure, but it is bounded by the context window. For a task that takes many steps or processes large documents, in-context memory alone is insufficient.
External memory uses a vector database such as Pinecone, Weaviate, or ChromaDB to store and retrieve information by semantic similarity. When the agent needs to recall something from a long earlier conversation, a previous session, or a large document corpus, it queries the vector store and injects the relevant results into the context. This is the retrieval-augmented memory pattern, and it is the most common approach for agents that need persistent knowledge.
Episodic memory stores summaries of past interactions, allowing the agent to recall what it did in previous sessions without storing every message verbatim. A lightweight implementation writes a structured summary to a database at the end of each session and retrieves relevant episodes at the start of the next one.
Working memory is an explicit scratchpad the agent maintains during a multi-step task: a structured record of what it has done, what it has found, and what it still needs to do. Externalising this into a structured object rather than relying purely on the conversation history significantly improves performance on complex tasks, because it prevents the model from losing track of earlier steps as the context grows.
The System Prompt: The Agent’s Constitution
The system prompt is the most underestimated component of agent design. It defines the agent’s identity, its available tools, the format it must use to call them, its reasoning style, its stopping conditions, and its constraints. A well-written system prompt for an agent typically includes a role definition, a tool registry with descriptions and invocation syntax, an explicit instruction to reason before acting, a rule specifying when to stop, and a safety boundary defining what the agent must not do.
A common mistake is writing a minimal system prompt and expecting the model to infer the rest. In an agentic loop, ambiguity in the system prompt compounds across steps: a model that is slightly uncertain about when to call a tool versus reason further will make inconsistent decisions, produce unpredictable behaviour, and be difficult to debug.
Observability and Safety: What Most Tutorials Skip
Two concerns that most introductory agent tutorials omit are observability and safety, and both matter enormously in production.
Observability means logging every step of the reasoning loop: what the model decided, which tool it called, what arguments it passed, and what the tool returned. Without structured logs, debugging a failed agent run is nearly impossible. Tools such as LangSmith, Weights and Biases, and Langfuse provide agent tracing infrastructure that makes this practical.
Safety in agentic systems means imposing hard limits on what the agent can do autonomously. Any action that is irreversible, such as sending an email, deleting a record, or executing a financial transaction, should require a human confirmation step before execution. This is not a limitation on capability; it is a precondition for deploying agents in environments where mistakes have real consequences.
Conclusion
An AI agent is a reasoning loop wrapped around an LLM, extended with tools that give it reach and memory systems that give it persistence. Building one from scratch, rather than dropping a framework in place, forces you to understand exactly what is happening at each step, which is the foundation of being able to debug, extend, and trust what you deploy. Start with a simple loop, a handful of clearly defined tools, and in-context memory. Add external memory and episodic summarisation as the complexity of your tasks demands it. Log everything. And never let an agent take an irreversible action without a human in the loop.
-
So You Want to Be an AI Engineer: A Subject-by-Subject Study Guide
A Career That Did Not Exist a Decade Ago
AI engineering is one of the fastest-growing roles in technology, with job openings increasing by 143% year on year in early 2026. Entry-level roles offer strong compensation, and the field spans virtually every industry, from healthcare and finance to education, manufacturing, and government. Yet the path into AI engineering is still poorly signposted. Many people who want to move into the field are unsure which subjects to prioritise, how deep to go, and where to start.
This guide cuts through that confusion. It is structured around the subjects and areas of knowledge that actually matter for AI engineering work in 2026: not a list of tools and buzzwords, but the underlying disciplines that give you durable capability regardless of which frameworks rise or fall in the years ahead.
Programming: The Non-Negotiable Starting Point
You should learn to code properly before moving on to anything AI-related. Python is a good choice because almost every AI library, framework, and tool is built for it first. The fundamentals to master include variables, functions, loops, data structures such as lists and dictionaries, object-oriented programming with classes and methods, file handling, and error management. This foundation typically takes two to three months of daily practice for complete beginners.
Beyond Python basics, you will need familiarity with version control via Git and GitHub, working in the terminal, writing clean and testable code, and understanding how to structure a software project. AI engineering is software engineering first; the AI parts sit on top of a solid programming foundation.
Mathematics: Three Areas That Underpin Everything
You do not need a mathematics PhD to build AI applications. You do need a working understanding of three areas.
Linear algebra is the mathematical language of neural networks. Matrices, vectors, dot products, matrix multiplication, eigenvalues, and transformations are the operations that underlie every forward pass through a model. You do not need to derive these from first principles, but you do need to know what they mean and how they behave.
Calculus and optimisation powers the training of every model you will ever use. Derivatives, the chain rule, gradients, and gradient descent are the mechanisms through which a model learns. A working understanding of why gradient descent converges, and what goes wrong when it does not, is essential for debugging training runs and configuring hyperparameters sensibly.
Probability and statistics governs how models handle uncertainty, make predictions, and are evaluated. Probability distributions, expectation, variance, Bayes’ theorem, hypothesis testing, and concepts like precision, recall, and AUC are the vocabulary of model evaluation. Understanding statistics is also what separates someone who can read a research paper from someone who cannot.
Machine Learning Fundamentals
Before working with large language models and APIs, you need a solid grounding in how machine learning systems actually learn. This means supervised learning (regression, classification), unsupervised learning (clustering, dimensionality reduction), overfitting and regularisation, cross-validation, and evaluation metrics. Understanding these concepts at a practical level gives you the mental model to diagnose model behaviour, choose the right approach for a given problem, and understand what LLMs are actually doing under the surface.
Successful AI engineers must write clean, efficient Python code, understand how machine learning and deep learning frameworks work in practice, and know how to prepare and handle data well. The two dominant deep learning frameworks are PyTorch and TensorFlow. PyTorch has become the preference for research and most production LLM work; TensorFlow remains widely used in enterprise deployment pipelines.
Large Language Models and the Modern AI Stack
This is where AI engineering in 2026 diverges most clearly from traditional machine learning engineering. AI engineers build chatbots, retrieval-augmented generation (RAG) pipelines, autonomous agents, and intelligent workflows that solve real problems. The subjects to study here include how transformer models work (covered in depth in our five-part LLM series on this blog), prompt engineering, the OpenAI and Anthropic APIs, LangChain and LlamaIndex for building LLM applications, vector databases such as Pinecone and Weaviate for semantic retrieval, and RAG architecture for grounding model outputs in specific knowledge bases.
This layer is evolving quickly, so the most important skill is learning how to learn: reading documentation, following model release notes, and building small projects with each new capability as it emerges.
Data Engineering
AI systems are only as good as the data they are built on. Data engineering covers how data is collected, cleaned, stored, and made available for training and inference. Key subjects include SQL for querying relational databases, pandas and NumPy for data manipulation in Python, data pipeline design, and working with both structured data (tables) and unstructured data (text, images, audio). Understanding data quality, deduplication, and how training data composition affects model behaviour is increasingly important as organisations build custom fine-tuned models for specific domains.
MLOps and Deployment
Building a model is only half the job. Getting it into production, keeping it running, and monitoring its behaviour in the real world is the other half, and it is where many AI projects fail. Core MLOps tools include Docker for containerisation, Kubernetes for orchestration, and cloud platforms such as AWS, Google Cloud, and Azure for deployment. You should also study CI/CD pipelines for model deployment, model versioning, logging and monitoring, and evaluation frameworks for detecting model drift and degradation in production.
Ethics, Safety, and AI Governance
Just as important are good communication skills and a solid grasp of ethical AI principles. Understanding algorithmic bias, fairness metrics, data privacy regulations such as GDPR and the EU AI Act, prompt injection and adversarial attacks, and the principles of responsible AI deployment is not optional for a practitioner who will be building systems that affect real people. Governance frameworks such as NIST AI RMF and ISO 42001 are increasingly appearing in enterprise procurement requirements, and familiarity with them signals professional maturity.
Where to Begin
The sequence that works for most people moving into AI engineering from another background is: Python fluency, then mathematics fundamentals, then machine learning basics, then the modern LLM stack, then MLOps. A portfolio of three to five complete projects showcasing deployment, monitoring, and handling of real-world challenges will demonstrate more to a hiring team than any single certification. Build something real at every stage of learning, and the path becomes much clearer than any roadmap can make it on paper.
-
Why AI Engineering Is Becoming One of the Most In-Demand Technology Skills
The Rise of AI Engineering
Artificial Intelligence has moved far beyond research laboratories and technology giants. Businesses of every size, from startups to global enterprises, are now actively looking for practical ways to integrate AI into their daily operations. As a result, AI Engineering has emerged as one of the fastest-growing and most in-demand career paths in the technology industry.
Unlike traditional software development, AI engineering focuses on building applications that can understand language, generate content, analyze data, and automate complex tasks using modern AI models. AI engineers combine software engineering skills with machine learning tools, APIs, cloud services, and prompt engineering to design intelligent applications that solve real business problems at scale.
How Large Language Models Changed Everything
One of the most significant shifts in AI engineering over the past two years has been the widespread adoption of Large Language Models (LLMs) such as ChatGPT, Claude, Gemini, and other generative AI systems. These pretrained models have fundamentally changed how developers build AI-powered applications.
Rather than training a model entirely from scratch, a process that previously required enormous datasets, specialized hardware, and months of work, developers can now integrate powerful LLMs into websites, mobile applications, business workflows, and customer support systems through simple API calls. This dramatically reduces development time, lowers the barrier to entry, and opens exciting new opportunities for innovation across every industry.
What Does an AI Engineer Actually Do?
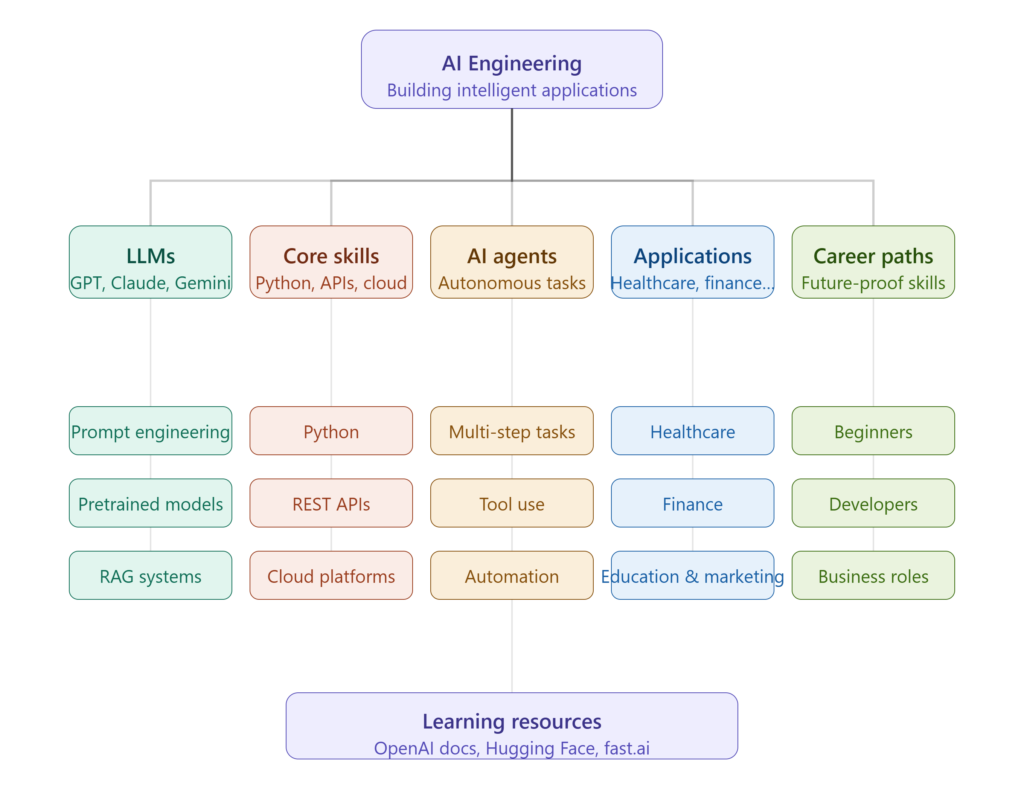
AI engineering is a broad and evolving discipline. Depending on the organization and project, an AI engineer’s responsibilities may include:
- Designing and building AI-powered applications that leverage LLMs, computer vision, or speech recognition
- Integrating external AI services via REST APIs and cloud platforms such as AWS, Google Cloud, and Microsoft Azure
- Managing and optimizing prompts to improve the accuracy, reliability, and safety of AI outputs
- Building Retrieval-Augmented Generation (RAG) systems that connect AI models to internal databases and knowledge bases
- Testing and evaluating AI outputs to ensure quality, consistency, and alignment with business requirements
- Ensuring solutions remain secure, ethical, and compliant with data privacy regulations
Core technical skills such as Python, REST APIs, SQL databases, and version control remain essential. However, the ability to communicate effectively with AI models — through clear, well-structured prompts and thoughtful system design — has become an equally important and increasingly sought-after skill.
The Growing Role of AI Agents
A particularly exciting trend in AI engineering is the rise of AI agents. Unlike simple chatbots that answer individual questions, AI agents can execute sequences of tasks autonomously. These tasks include retrieving information from the web, analyzing uploaded documents, drafting reports, sending notifications, and interacting with multiple software systems in a coordinated workflow.
Organizations across industries are already exploring agent-based automation to improve productivity, reduce repetitive work, and enable their teams to focus on higher-value activities. For AI engineers, understanding how to design, deploy, and manage multi-step agent workflows is quickly becoming one of the most valuable skills in the field.
Career Opportunities in AI Engineering
For students and professionals looking to build future-proof careers, AI engineering offers a compelling combination of programming, creativity, problem-solving, and continuous learning. The demand for qualified AI engineers is expected to grow significantly across sectors including healthcare, finance, education, manufacturing, marketing, and government.
You do not need to have a traditional machine learning background to enter this field. Many successful AI engineers come from web development, data analysis, or business backgrounds and build their AI skills progressively. They start with APIs and prompt engineering before advancing to more complex topics like fine-tuning, embeddings, and agent frameworks.
Where to Start Learning AI Engineering
If you want to explore AI engineering in greater depth, two of the best starting points are the OpenAI Developer Platform and the Hugging Face Documentation. Both offer practical tutorials, code examples, and up-to-date guidance for developers building modern AI applications.
The most important step is simply to start building. Experiment with APIs, explore open-source models, and work on small projects that solve real problems. Practical experience, more than any certification, is what will set you apart in this fast-moving field.