The Profound Mathematics of LLM Watermarking: How AI Text Hides an Invisible Signature
A Signal Hidden in Plain Sight
Every token a language model generates comes from a probability distribution. LLM watermarking exploits this single fact with remarkable precision. It biases that distribution just enough to leave a statistical fingerprint. Human readers cannot see it. Trained detectors can find it with near certainty. Understanding how this actually works requires going past the marketing language entirely. It requires real probability theory, real hypothesis testing, and a careful look at what “invisible” actually means in a mathematical sense.
This article goes deep. LLM watermarking sits at the intersection of cryptography, statistics, and information theory, and it deserves treatment at that level.
The Core Idea: Biasing a Distribution Without Breaking It
At each generation step, a language model produces a probability distribution over its entire vocabulary, denoted P. Standard sampling draws the next token directly from this distribution. LLM watermarking intervenes before sampling occurs, but after the distribution has been computed.
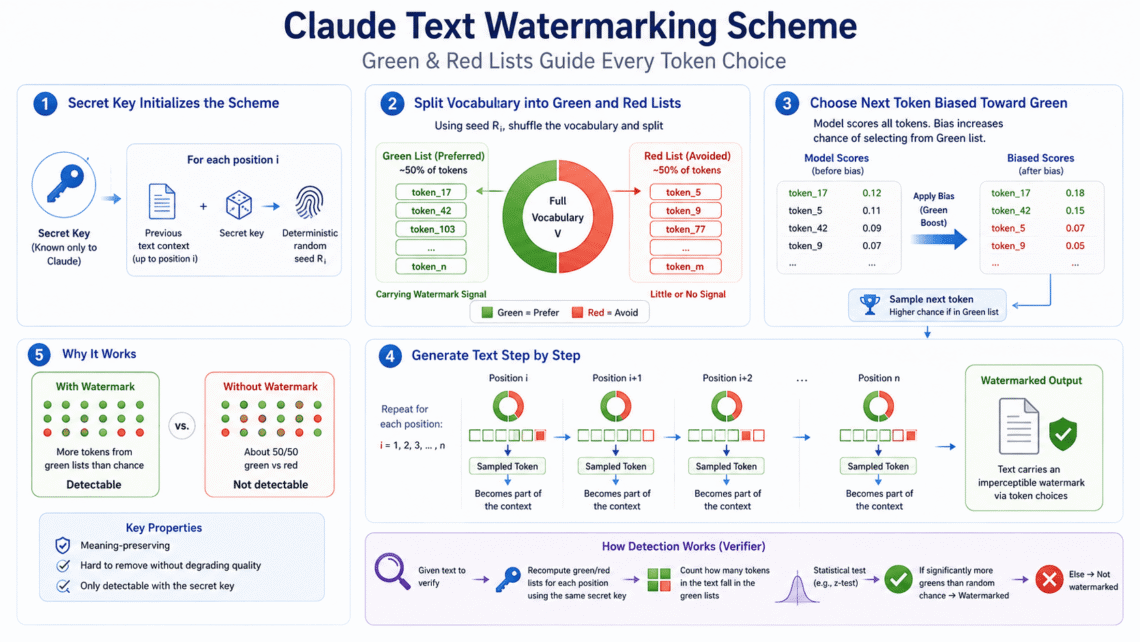
The foundational approach, introduced by Kirchenbauer, Geiping, Wen, Katz, Miers, and Goldstein in 2023, works through vocabulary partitioning. At every generation step, a pseudorandom function f, seeded by a secret key k and the preceding token, splits the entire vocabulary V into two disjoint sets. One is called the green list, with size γ|V|. The other is the red list, with size (1−γ)|V|. Typically γ equals 0.25 or 0.5.
The model does not simply choose only from the green list. That would destroy text quality immediately. Instead, it applies a soft bias. Every token in the green list receives a boost to its logit value before the softmax function converts logits into probabilities. Formally, for a green-list token, the modified probability becomes:
Here δ is the watermark strength parameter, and Z is a normalization constant ensuring probabilities still sum to one. A larger δ produces a stronger, more detectable watermark. It also increases the risk of degrading text quality, since the model is nudged away from its true optimal token choice more forcefully.
Why Entropy Determines Everything
Here is where LLM watermarking becomes genuinely elegant rather than crude. Not every token position can absorb a watermark bias equally well. Consider the phrase “Barack” followed by “Obama”. The probability of “Obama” as the next token approaches certainty. This is a low-entropy prediction. Forcing “Obama” onto the red list would produce obviously broken, unnatural text, immediately visible to any reader.
Kirchenbauer and colleagues addressed this directly using a concept called spike entropy. This measures how concentrated a probability distribution is. Low spike entropy means the model has essentially one dominant choice. High spike entropy means many tokens are roughly equally plausible.
The watermark strength effectively scales with this entropy. When spike entropy is low, the soft rule barely shifts probabilities at all, since P(w) already dominates regardless of e^δ. When spike entropy is high, many tokens sit close together in probability. The green list bias then meaningfully redirects sampling toward green tokens without producing any single obviously wrong choice. This is precisely why highly creative, high-entropy text carries a strong watermark signal, while highly constrained, low-entropy text, like a phone number or a famous quote, resists watermarking almost entirely LLM watermarking.
Detection as a Hypothesis Test
The genuine mathematical power of LLM watermarking becomes visible at detection time. A verifier does not need access to the original model or its output probabilities at all. They only need the secret key k and the text itself.
Detection is formally cast as a hypothesis test. The null hypothesis H0 states the text was generated with no knowledge of the green-list rule, meaning it is either human-written or produced by an unwatermarked model. The alternative hypothesis H1 states the text was generated using the watermarking scheme.
For a text of T tokens, the detector counts how many tokens fall into the green list, denoted |x|_G. Under H0, each token independently has probability γ of landing in the green list purely by chance, since the partition itself is essentially random relative to genuine human writing. This means |x|_G follows a binomial distribution B(T, γ) under the null hypothesis.
The classic Kirchenbauer detection statistic uses a one-proportion z-test:
This formula should look familiar to anyone who has studied introductory statistics. It is the standard z-score for a sample proportion test. The numerator measures how far the observed green-token count deviates from its expected value under pure chance. The denominator normalizes by the standard deviation of a binomial distribution.
Under H0, this z-score asymptotically follows a standard normal distribution, N(0,1). A verifier sets a detection threshold, often z > 4, corresponding to an extraordinarily low false positive probability, roughly one in tens of thousands. If the observed z-score exceeds that threshold, H0 is rejected. The text is classified as watermarked with high statistical confidence LLM watermarking.
The corresponding p-value is computed directly as:
This p-value has a genuinely rigorous interpretation. It represents the probability of observing a green-token count this extreme, purely by random chance, if the text were not actually watermarked.
The Robustness Problem and the Unigram Fix
The original scheme has one notable weakness worth examining mathematically. Because the green-red partition depends on the preceding token, an attacker who paraphrases the text, changing word order or substituting synonyms, can disrupt the pseudorandom function’s context window. This weakens or destroys the watermark signal.
Zhao and colleagues proposed a fix in their Unigram watermark scheme. Rather than conditioning the partition on the previous token, the green-red split becomes fixed and global, independent of context entirely. This produces a modified detection statistic:z=Tγ(1−γ)∣x∣G−γT
The formula looks structurally identical, but the underlying green list itself no longer shifts token by token. This trades some theoretical unpredictability for genuine robustness against reordering attacks. It illustrates a fundamental tension running through all LLM watermarking research. Stronger security guarantees and stronger robustness guarantees often pull in opposite directions.
Distortion-Free Watermarking: The Gumbel Approach
A separate and mathematically distinct family of LLM watermarking schemes takes a fundamentally different approach. Rather than biasing the output distribution, these methods aim for what researchers call distortion-free watermarking. The marginal distribution of generated text remains provably identical to the unwatermarked model.
Scott Aaronson’s approach, developed during his tenure at OpenAI, uses the Gumbel-max trick. Instead of sampling directly from P, the method generates a sequence of pseudorandom values u_1, u_2, …, u_|V|, one for each vocabulary token, deterministically derived from the secret key and context. The selected token becomes:
This construction has a remarkable mathematical property. When u_i values are drawn uniformly from [0,1], this selection rule produces exactly the same marginal token distribution as standard sampling from P. No detectable statistical shift exists in the output distribution alone. The watermark lives entirely in the correlation between the chosen tokens and the pseudorandom sequence u, a correlation invisible without the secret key, but detectable with it through a separate statistical test based on the Gumbel values themselves.
This is genuinely important theoretically. It means distortion-free schemes carry zero cost to text quality in expectation, unlike the green-red list approach, which necessarily introduces some bias, however small, to create its detectable signal.
The Detection Power Trade-off
Every LLM watermarking scheme faces an unavoidable statistical trade-off, formalized through the relationship between Type I error (false positives) and Type II error (false negatives). Security-critical deployments demand extremely low false positive rates, since falsely accusing a human-written text of being AI-generated carries real reputational and legal cost.
This constraint directly limits detection sensitivity. The ROC curve, plotting true positive rate against false positive rate as the detection threshold varies, captures this trade-off precisely. The area under this curve, AUC, summarizes overall detector quality across all possible thresholds. Empirical research has found a genuine gap between theoretical asymptotic guarantees and observed false positive rates in practice, since the z-score’s normal approximation assumes sufficiently large T. Short text segments, tweets or brief chat responses, often violate this assumption, requiring more careful finite-sample statistical treatment than the simple asymptotic formula provides.
The Deeper Theoretical Question
LLM watermarking research increasingly frames detection not as a single fixed test, but as a general statistical estimation problem. Recent work reformulates the entire family of schemes around a common structure. A score statistic is computed from the candidate text. A p-value is derived under the null hypothesis. A threshold, calibrated to a desired false positive rate, determines the final classification.
This unification matters because it reveals something genuinely important. Every LLM watermarking scheme, regardless of its specific mechanism, green-red lists, Gumbel sampling, or newer multilayer approaches like BiMark, reduces fundamentally to the same statistical question. Given this candidate text, and this secret key, how surprising would this pattern be under pure chance alone? The elegance of the entire field rests on answering that single question with mathematical rigor, using tools drawn directly from classical hypothesis testing, extended carefully into the high-dimensional, sequential setting that language generation demands.
Conclusion
LLM watermarking is not a superficial trick layered onto AI text after the fact. It is a genuine statistical construction, built directly into the sampling process itself, exploiting the mathematics of entropy, pseudorandom functions, and hypothesis testing to leave a signature that survives detection while remaining invisible to ordinary reading. The green-red list method reveals how entropy governs where a watermark can hide. The Gumbel-based distortion-free approach reveals that watermarking need not cost anything in expected text quality at all. And the unifying hypothesis-testing framework reveals that, beneath every clever implementation, the same rigorous statistical question is always being asked.
This article has deliberately stopped short of one crucial question. How well does any of this actually hold up against a determined adversary trying to remove the signal? That question, covering paraphrasing attacks, token substitution, and the genuine limits of watermark robustness, deserves its own dedicated treatment.


You May Also Like
The Profound Question of AI Consciousness: What Machine Minds Reveal About Our Own
The ARC AGI Benchmark: 2 Powerful Tests Exposing AI’s Real Reasoning Gap