-
Who Is Legally Responsible for Autonomous Vehicle Accidents? A Critical Guide to AI, Ethics, and the Law
Sally Knew the Road. But Who Was Responsible?
In 1953, Isaac Asimov published a short story called “Sally” in Fantastic magazine. In it, self-driving cars with positronic brains roam a farm for retired automobiles, developing personalities and emotional responses. When a villainous character attempts to exploit them, Sally and the other cars act to protect themselves and the humans they care for. Asimov, as he so often did, had seen something clearly: that autonomous vehicles capable of independent action would inevitably raise questions that went far beyond engineering. Questions about agency, intention, and most pressingly, responsibility.
Seventy years later, those questions are no longer philosophical. They are legal, regulatory, and deeply urgent. Autonomous vehicle accidents liability has become one of the most contested areas in technology law, as self-driving cars move from test tracks to public roads and courts, insurance companies, and legislators scramble to answer the question Asimov posed in fiction: when an autonomous vehicle causes harm, who is accountable?
The Scale of the Problem
Autonomous vehicles are no longer experimental. Waymo, the autonomous driving subsidiary of Alphabet, completed over four million fully driverless trips in 2024 and is currently expanding into new cities including Miami and Tokyo. Tesla’s Full Self-Driving system is active on hundreds of thousands of vehicles on public roads. In 2025, the US National Highway Traffic Safety Administration (NHTSA) reported receiving over 2,500 incident reports involving vehicles with automated driving features, a figure that represents only a fraction of actual incidents due to inconsistent reporting requirements.
The accidents are real and, in some cases, fatal. In 2023, a Cruise autonomous vehicle in San Francisco struck a pedestrian who had already been hit by another car, then dragged her 20 feet before stopping. California’s Department of Motor Vehicles revoked Cruise’s operating licence. General Motors ultimately shut down the Cruise unit. In 2024, a Waymo robotaxi in Phoenix struck a cyclist who had run a red light. The cyclist was injured but survived. Both incidents raised the same fundamental question that courts and regulators have yet to answer cleanly: who is responsible for autonomous vehicle accidents when the vehicle itself made the decision?
The Legal Framework in the United States
Under current US law, autonomous vehicle accidents liability falls into a patchwork of state-level frameworks with no coherent federal standard. This is partly because US traffic law has historically been a state matter, and partly because Congress has repeatedly failed to pass comprehensive autonomous vehicle legislation, most recently when the SELF DRIVE Act stalled in 2021.
In practice, autonomous vehicle accidents liability in the US currently resolves through three legal theories. The first is product liability: the argument that the autonomous vehicle system was defective and the manufacturer is responsible, in the same way that a tyre manufacturer is liable for a blowout caused by a manufacturing defect.
The second is negligence, directed either at the manufacturer for deploying an inadequately tested system, or at the human operator, if one was present, for failing to intervene. The third is agency liability, an emerging theory that treats the vehicle’s AI as acting on behalf of its manufacturer, making the manufacturer responsible for the AI’s decisions the way an employer is responsible for an employee’s actions in the course of their work.
Most autonomous vehicle accident lawsuits in the US have settled before reaching verdict, which has slowed the development of clear case law. Arizona, California, and Texas have enacted their own autonomous vehicle frameworks, but these differ significantly on questions including whether a human must be present in the vehicle, what data must be retained after an incident, and who must report accidents and to whom.
The NHTSA’s Standing General Order, introduced in 2021 and strengthened in 2023, now requires manufacturers to report all crashes involving automated driving systems within one day if an airbag deployed or a fatality occurred. This has dramatically improved data collection but has not resolved the underlying autonomous vehicle accidents liability question.
The European Approach: Stricter, Clearer, but Still Evolving
The European Union has taken a more structured approach to autonomous vehicle accidents liability. The EU’s updated Product Liability Directive, which came into force in December 2024, explicitly covers AI systems and software as “products,” meaning that manufacturers of autonomous vehicle systems can be held liable for damages caused by defects in their AI, including defects that arise from inadequate training data, flawed algorithms, or failure to update the system against known risks.
Germany moved first among EU member states, passing the Autonomous Driving Act in 2021, which created a legal framework for Level 4 autonomous vehicles (those capable of driving themselves in defined conditions without human intervention) and established that when an autonomous vehicle accidents liability question arises, the vehicle owner’s compulsory insurance covers damages, with the right to pursue the manufacturer if a technical defect is found. Several other EU countries are following Germany’s model.
The EU AI Act, whose high-risk provisions took full effect in August 2026, classifies autonomous vehicle AI systems as high-risk, requiring conformity assessments, extensive documentation, transparency obligations, and post-market monitoring. For autonomous vehicle accidents liability specifically, the Act requires that high-risk AI systems maintain logs sufficient to trace decisions that led to incidents, which for the first time gives courts access to the AI’s decision record rather than relying solely on witness accounts and physical evidence.
Ethical Dimensions: The Trolley Problem at 70 Miles Per Hour
The legal question of autonomous vehicle accidents liability cannot be cleanly separated from the ethical one. Autonomous vehicles must, by design, make split-second decisions that in human drivers arise from instinct and moral intuition. The philosophical thought experiment known as the trolley problem, in which an actor must choose between allowing one harm or actively causing a lesser one, is not abstract for an autonomous vehicle. It is a real design decision encoded in the vehicle’s decision-making algorithm.
In 2016, a survey published in Science found that while most people agreed autonomous vehicles should be programmed to minimise total casualties, they were less willing to purchase a vehicle programmed to sacrifice its own occupant to save pedestrians. This tension, between what is collectively optimal and what is individually acceptable, has no clean resolution.
Asimov’s Three Laws of Robotics, which he spent a career demonstrating were insufficient for the complexity of real-world moral situations, come to mind here. Sally’s cars protected their passengers and themselves. A real autonomous vehicle’s priority hierarchy must be set by someone, and whoever sets it is making an ethical choice with legal consequences.
The MIT Moral Machine experiment, which collected 40 million decisions from participants in 233 countries about autonomous vehicle ethical dilemmas, found significant cultural variation in how people prioritised pedestrians versus passengers, the young versus the old, and law-abiding versus law-breaking road users. There is no universal answer. And yet autonomous vehicle manufacturers must encode one.
Reducing Autonomous Vehicle Accidents: What Is Actually Working
Despite the legal and ethical complexity, the safety record of mature autonomous vehicle systems is improving. Waymo published a peer-reviewed study in 2024 showing that its vehicles were involved in significantly fewer injury-causing crashes per mile than human-driven vehicles in comparable environments. The key advances driving this improvement include higher-resolution sensor fusion combining LiDAR, radar, and cameras with redundant processing; improved simulation training using synthetic edge-case scenarios that would be dangerous or impossible to stage in reality; and V2X (vehicle-to-everything) communication, which allows vehicles to share real-time information about hazards, traffic conditions, and each other’s positions.
Regulators are also improving the frameworks around incident reporting and investigation. The NHTSA’s new autonomous vehicle data portal, launched in 2025, makes incident data publicly available in near real-time, enabling researchers to identify failure patterns and manufacturers to issue targeted system updates far more quickly than the traditional recall process allows.
Conclusion: Asimov’s Question, Still Unanswered
Autonomous vehicle accidents liability remains one of the most unresolved legal questions in modern technology law. The US is moving toward resolution through litigation and piecemeal state legislation; the EU is moving toward it through structured regulation. Neither has yet produced a framework that satisfactorily answers the core question: when an AI makes a decision that injures or kills someone, who is responsible?
Asimov’s Sally knew what she wanted to do and did it. The humans around her were left to reckon with the consequences. In 2026, we are in precisely that position, only the stakes are not fictional, the roads are public, and the answer matters enormously to everyone who shares them.
-
3 Alarming Environmental Costs of AI: Data Centers, Drought, and Community Backlash
The Infrastructure Behind the Intelligence
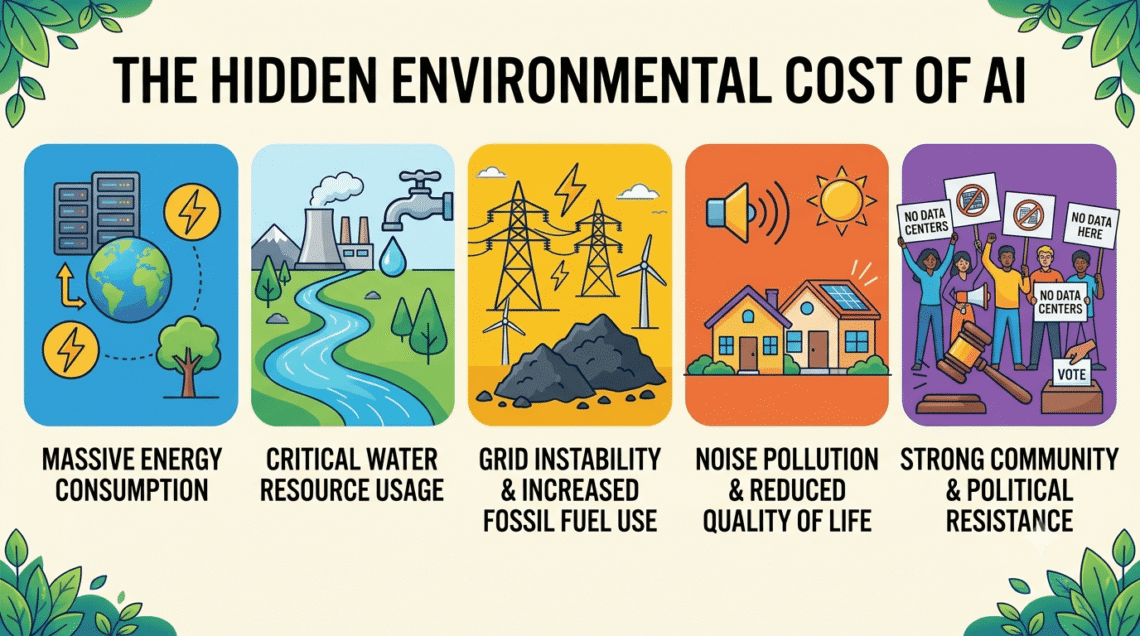
Every time you ask an AI chatbot a question, generate an image, or run an AI-powered search, a data center somewhere in the world processes that request. These facilities, enormous buildings packed with servers, networking equipment, and cooling infrastructure, are the physical backbone of the AI revolution. They are also, increasingly, the source of one of the most consequential and underreported stories of the AI era: the environmental impact of AI data centers and the social cost of building and running them at scale.
The numbers have reached a scale that is difficult to comprehend. A UN report estimated that data centers required for AI globally could consume 945 terawatt-hours of electricity annually by 2030, roughly twice France’s entire 2025 power consumption, with a carbon footprint that would require some 6.7 billion trees grown over ten years to offset, a water footprint equal to the annual domestic needs of 1.3 billion people in Sub-Saharan Africa, and a land footprint of more than 14,500 square kilometres. That is not a distant forecast. The International Energy Agency found that electricity consumption from AI-focused data centers grew by approximately 50% in 2025 alone.
Water: The Hidden Resource Crisis
Of all the resources data centers consume, water is the one generating the most urgent local conflicts. Data centers use water in two ways: directly, through evaporative cooling systems that spray water over hot air to dissipate heat, and indirectly, through the power plants that generate their electricity, which also require water for cooling. One estimate shows that a single data center could consume up to 5 million gallons of water per day, roughly equivalent to the daily use of a town with 50,000 residents.
In Idaho, the collision between AI infrastructure and water scarcity has become a defining political issue. According to the Idaho Department of Water Resources’ 2026 Water Supply Outlook Report, this year’s snowpack ranks among the 10 lowest on record, and streamflow forecasts point toward continued drought conditions. Into this already stressed environment, Meta is building a massive facility in Kuna, Idaho, scheduled to open in late 2026, competing for the same rivers, aquifers, and reservoirs that Idaho’s farms and families depend on.
The precedent from Oregon is sobering. Google’s data centers in The Dalles, Oregon, consumed 355 million gallons of water in 2021 alone, accounting for 29% of the city’s total water use, during a period when Oregon’s drought intensified for five consecutive years. A water official told the Idaho Capital Sun that data centers use such high volumes that their wastewater discharge can overwhelm small municipal treatment plants, leading to untreated effluent entering waterways.
In Tennessee, the Tennessee Valley Authority recently reported that runoff levels are currently the fourth-lowest recorded in 152 years of record-keeping. Tennessee is simultaneously becoming a major hub for AI infrastructure, including AI data centers, which brings us to the most controversial data center story in America right now.
Memphis: A Community Under Pressure
The environmental impact of AI data centers has no clearer illustration than what is happening in Memphis, Tennessee. The xAI Colossus facility in Memphis, built by Elon Musk’s AI company in a neighbourhood called Boxtown, has become a flashpoint for the national debate. Boxtown is a community founded by formerly enslaved people, and before Colossus arrived, the area already hosted an oil refinery and a steel mill. Since opening in 2024, the facility has become a top polluter in Memphis’s historically Black neighbourhood, and the Southern Environmental Law Center and others are now suing the company.
Many residents of Memphis, including city council members, say they were given no input about the project or its potential impacts on the city. The concerns are wide-ranging: potential contamination of the Memphis Sand Aquifer, one of the largest and purest groundwater sources in the United States; the use of gas turbines to power the facility; and the noise and air quality impacts on surrounding neighbourhoods that already carry a disproportionate industrial burden.
“This continues a legacy of billion-dollar conglomerates who think that they can do whatever they want to do, and the community is just not to be considered,” KeShaun Pearson, executive director of Memphis Community Against Pollution, told TIME. “They treat southwest Memphis as just a corporate watering hole.”
Electricity: Rising Bills and Grid Instability
The electricity demands of AI data centers and related infrastructure are reshaping energy markets in ways that ordinary consumers are only beginning to feel. In parts of the PJM power market, a federal watchdog has warned that data center demand is already helping drive sharp increases in electricity prices. In late June 2026, Virginia lawmakers passed a new energy consumption tax on data centers of $0.011 per kilowatt hour used per month, expected to generate around $600 million of revenue each year.
The grid pressure is producing decisions that undermine climate commitments. Data centers’ energy demands have driven some utilities to delay shuttering fossil fuel power plants and have prompted proposals to revive retired ones. The proposed Stargate data center power plant in Abilene, Texas, could emit more than 7.8 million tons of greenhouse gases per year, equivalent to the pollution from approximately 2 million cars annually.
Noise, Light, and the Quality of Life Toll Exacted by AI Data Centers
Beyond the headline figures on water and electricity lies a quieter but deeply felt set of concerns. AI data centers produce constant low-frequency noise from cooling fans and electrical equipment, running 24 hours a day, seven days a week. U.S. News reported that 16% of residents near data centers specifically mention noise pollution, air pollution, and water pollution as related environmental concerns. In Peculiar, Missouri, residents organised to stop a AI data center proposal, citing concerns around noise and light pollution, health impacts, property values, and energy use, ultimately securing a unanimous city council rejection in September 2024.
The housing market is feeling the pressure too. In Abilene, Texas, where the massive Stargate AI data center is under construction, the local housing crisis is worsening as construction workers and technology employees flood a small city’s rental market.
Communities Are Fighting Back Against AI Data Centers
The scale of community resistance to AI data center development has crossed a threshold that the technology industry did not anticipate. Research firm Data Center Watch found that between March and June 2025, community opposition led to $98 billion in data center projects being blocked or delayed, and at least 25 projects were cancelled in 2025 in response to local objections. A March 2026 report from Data Center Watch counted at least 75 projects facing community resistance during the first quarter of 2026 alone.
Political responses are escalating alongside grassroots action. Senators Bernie Sanders and Alexandria Ocasio-Cortez introduced legislation in March 2026 proposing a moratorium on all new data center construction nationwide until AI safeguards, including worker and environmental protections, are in place. At least nine states are considering legislation to slow, delay, or limit data center construction. In Michigan, the Ypsilanti Community Utilities Authority passed a yearlong halt to water and sewer services for data centers in April 2026. In Missouri, voters in Festus removed several city council members after they supported a new data centre despite resident opposition.
Communities are being asked to conserve water and absorb higher living costs while some of the world’s most valuable technology companies secure the power and water they need to fuel the AI boom. The tension between AI’s transformative promise and its extractive infrastructure demands is no longer abstract. It is playing out in town halls, courtrooms, and ballot boxes across the United States and beyond.
What Needs to Change
The technology industry’s standard response to these concerns, that AI data centers bring jobs, tax revenue, and long-term investment, and that companies are working on cleaner energy and more efficient cooling, is not false. Some facilities are genuinely making progress: closed-loop cooling systems that recycle water rather than evaporating it, direct deals with renewable energy providers, and waste heat recovery programs that supply warmth to nearby buildings. But the pace of these improvements is not matching the pace of deployment, and there is greater need for responsible AI governance.
Critics counter that the pace of AI data center and related infrastructure growth is moving faster than local governments, utilities, and water systems can realistically absorb. What is missing is a federal framework that requires environmental impact assessment before construction, mandates water efficiency standards, provides transparent disclosure of resource consumption, and ensures that the communities hosting these facilities share meaningfully in their economic benefits. Until that framework exists, the communities absorbing AI’s physical footprint will continue to bear costs that the industry’s balance sheets do not reflect.
-
7 Powerful Steps to Build an AI Agent from Scratch in Python
Why Build an AI Agent from Scratch?
If you want to build an AI agent that actually works in production, the worst place to start is a pre-packaged framework that hides what is happening beneath the surface. Frameworks are useful once you understand what they are abstracting. Before that point, they make debugging nearly impossible and leave you unable to explain your own system’s behaviour.
This guide walks through seven concrete steps to build an AI agent from scratch using Python. By the end, you will understand precisely how each component of the agent works, how they connect, and what goes wrong when they do not. Whether you are a software engineer exploring AI, or a practising ML engineer who wants to move beyond single-turn API calls, building an AI agent from scratch is one of the most productive things you can do to advance your practical skills in 2026.
Step 1: Understand What an AI Agent Actually Is
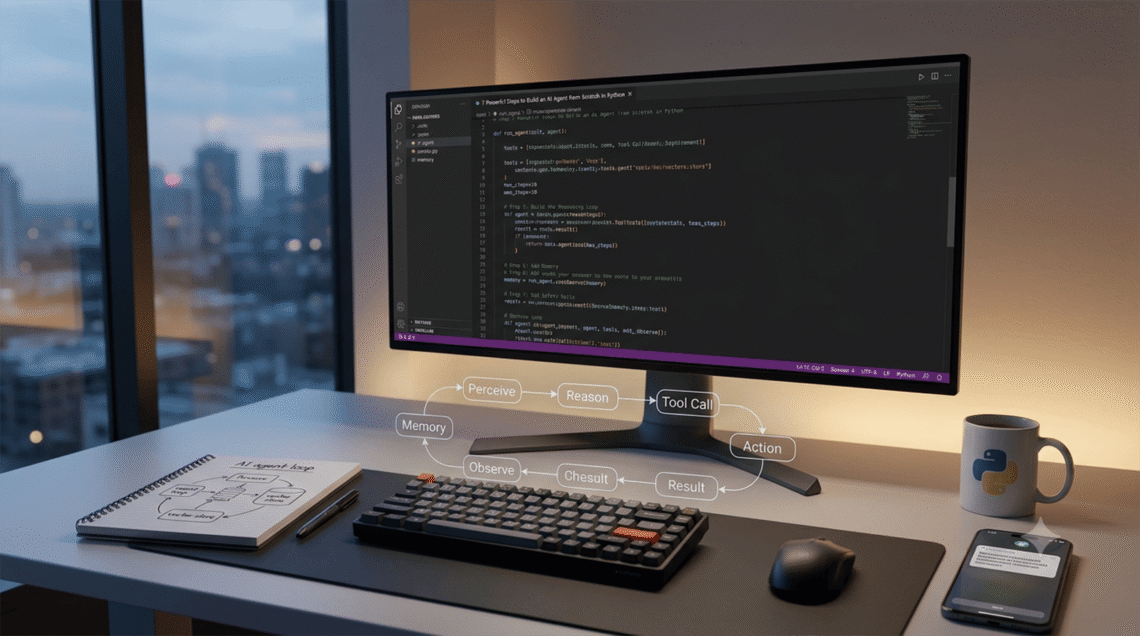
Before writing a single line of code, you need a clear mental model. An AI agent is not a chatbot that answers one question at a time. It is a reasoning system that perceives a situation, selects an action, executes it, observes the result, and decides what to do next, repeating this loop until the task is complete.
The three components every AI agent needs are tools (functions it can call to interact with the world), memory (a record of what has happened so far), and a reasoning loop (the logic that connects perception to action). When you build an AI agent from scratch, you are constructing all three of these components yourself, rather than inheriting someone else’s implementation.
Step 2: Choose Your LLM and Set Up Your Environment
To build an AI agent from scratch, you need access to an LLM that supports tool calling. The OpenAI API and the Anthropic API both provide native tool-calling interfaces that tell the model when and how to invoke external functions. Set up your Python environment with the relevant SDK:
pip install openai anthropic python-dotenvStore your API keys in a
.envfile and load them withpython-dotenv. Never hardcode credentials in your agent code, as this is a security risk that becomes serious the moment your agent has access to external systems.Step 3: Define Your Tools
Tools are the hands of your AI agent. Each tool is a Python function that the agent can call at runtime. Define them clearly, because the model reads your descriptions to decide when to use each one:
tools = [
    {
        "type": "function",
        "function": {
            "name": "web_search",
            "description": "Search the web for current information on any topic.",
            "parameters": {
                "type": "object",
                "properties": {
                    "query": {
                        "type": "string",
                        "description": "The search query to send."
                    }
                },
                "required": ["query"]
            }
        }
    }
]
Write tool descriptions as if you are explaining the function to a capable but literal colleague. Vague descriptions produce inconsistent tool selection, which is one of the most common failure modes when you build an AI agent from scratch.
Step 4: Write the System Prompt
The system prompt is the agent’s constitution. It defines its identity, its available tools, the format it must use to call them, and the conditions under which it should stop. A minimal but effective system prompt for a research agent looks like this:
You are a research assistant with access to web search.
Think step by step before acting. Use the web_search tool
to find current information. When you have enough information
to answer the task fully, return a final answer clearly labelled
as "Final Answer:". Never guess when you can search.
When you build an AI agent from scratch, the system prompt deserves as much attention as the code. A poorly written prompt produces unpredictable reasoning regardless of how well the rest of the system is engineered.
Step 5: Build the Reasoning Loop
The reasoning loop is the core of the agent. It sends the current conversation to the LLM, parses its response for tool calls, executes the tools, appends the results, and repeats:
def run_agent(task: str, tools: list, tool_functions: dict,
              max_steps: int = 10) -> str:

    messages = [
        {"role": "system", "content": SYSTEM_PROMPT},
        {"role": "user",   "content": task}
    ]

    for step in range(max_steps):
        response = client.chat.completions.create(
            model="gpt-4o",
            messages=messages,
            tools=tools
        )
        message = response.choices[0].message

        if message.tool_calls is None:
            return message.content  # final answer reached

        for tool_call in message.tool_calls:
            fn_name = tool_call.function.name
            fn_args = json.loads(tool_call.function.arguments)
            result  = tool_functions[fn_name](**fn_args)

            messages.append(message)
            messages.append({
                "role": "tool",
                "tool_call_id": tool_call.id,
                "content": str(result)
            })

    return "Max steps reached."
Notice the
max_stepsguard. Every time you build an AI agent from scratch, this is non-negotiable. Without it, a confused agent will spin indefinitely and consume tokens until it hits a rate limit or your budget runs out.Step 6: Add Memory
In-context memory is built into the loop above: the entire conversation history is passed to the LLM at each step, giving it full access to everything that has happened. For longer tasks or multi-session agents, you need external memory.
The simplest form of external memory is a vector store. At the end of each session, summarise the key findings and store them as embeddings in a database such as ChromaDB or Pinecone. At the start of the next session, retrieve the most relevant summaries and inject them into the context:
import chromadb

client_db = chromadb.Client()
collection = client_db.create_collection("agent_memory")

def save_memory(content: str, session_id: str):
    collection.add(
        documents=[content],
        ids=[session_id]
    )

def retrieve_memory(query: str, n: int = 3) -> list[str]:
    results = collection.query(query_texts=[query], n_results=n)
    return results["documents"][0]
When you build an AI agent from scratch with persistent memory, you move from a stateless tool into a system that genuinely learns from experience across sessions.
Step 7: Add Observability and Safety Rails
The final step before deploying is instrumentation. Log every step of the reasoning loop: what the model decided, which tool it called, what arguments it passed, and what the tool returned. Without structured logs, debugging a failed agent run is nearly impossible.
Safety rails are equally important. Any action that is irreversible, sending an email, modifying a database record, executing a financial transaction, should route through a human confirmation step before execution. Implementing this is straightforward: before calling any write-action tool, prompt the user for explicit approval and only proceed if it is granted.
Build an AI Agent from Scratch: What Comes Next
Once you have a working agent using these seven steps, the natural progression is to add more tools, introduce parallel tool execution, implement re-ranking for memory retrieval, and explore multi-agent architectures where specialised agents collaborate on complex tasks. Each of those extensions builds directly on the foundation covered here.
The most important thing is to start. Build an AI agent from scratch on a small, bounded task. Break it deliberately. Fix it. Then extend it. That cycle of build, break, and fix is how engineering intuition develops, and intuition is what separates an AI engineer who can ship from one who can only read about it.
-
Why Human-in-the-Loop Is the Most Critical Safeguard in the Age of Agentic AI
The Assumption That Is Breaking Down
For much of the past two years, enterprise AI teams have offered a reassuring answer to concerns about autonomous AI systems: “There is a human in the loop.” The phrase became a kind of talisman, a two-sentence ethics policy that seemed to resolve questions about accountability, safety, and governance in one neat stroke.
In 2026, that assumption is breaking down in plain sight. Companies implementing AI agents will initially require human approval for every action, but the human-in-the-loop safety mechanism that many organisations are relying on to control AI agents will largely fail due to approval fatigue. Agents will be operating with minimal supervision despite policies suggesting otherwise. The problem is not that human oversight is a bad idea. It is that organisations have confused the concept with the practice, and the gap between the two is where the real risk lives.
What Human-in-the-Loop Actually Means
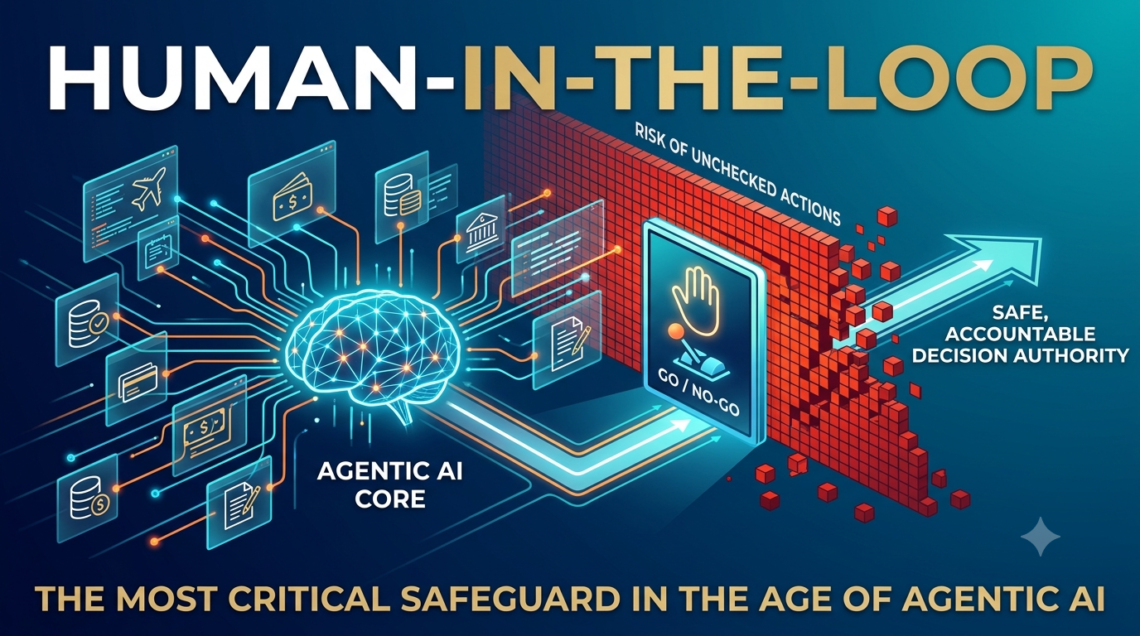
Human-in-the-Loop (HITL) is an AI governance approach where trained humans retain decision authority over high-risk AI agent actions, providing oversight through timely context, intervention authority, and defensible rationale. Three elements are required simultaneously: the human must have enough context to make a meaningful decision, the authority to actually stop or redirect the AI’s action, and a documented rationale for whatever they decide. Remove any one of the three and you do not have governance. You have theatre.
The distinction between two related concepts matters here. Human-in-the-loop requires a human to approve or authorise an action before the AI system executes it: the system pauses and waits. Human-on-the-loop allows the AI to act autonomously while a human monitors outputs and can intervene after the fact. The challenge with agentic AI is that agents blur these boundaries. An agent that books a flight and then negotiates a vendor contract within the same workflow requires different oversight levels at different steps. The oversight model must be dynamic, not a single blanket policy applied uniformly across every action.
The Agentic AI Problem
The stakes of getting this wrong have risen sharply as AI moves from producing text to taking actions. Agentic AI raises the stakes significantly. AI agents take independent actions, booking flights, moving money, modifying infrastructure, which means oversight failures have immediate, real-world consequences.
In simulation testing, AI agents fail multi-step tasks nearly 70% of the time, a statistic that should give pause to anyone deploying them in production without robust human checkpoints. Amazon convened an internal review after a string of retail site outages apparently caused by AI-assisted coding tools, following several highly visible failures and a growing recognition inside the company that safeguards around generative AI in production systems are inadequate.
The most significant failures of the next decade will not happen because models are wrong. They will happen because the decision authority was exercised too early. Modern AI systems are exceptionally effective at prediction. They identify patterns, score risk, and surface anomalies at a scale no human team could match. But prediction is not the same as authority.
Automation Bias: The Hidden Enemy
Even when a human is genuinely present in the loop, a well-documented psychological phenomenon undermines the value of their oversight. Humans in the loop tend to exhibit automation bias, meaning that they often place more trust in the AI system than is warranted. A human reviewer who has approved 200 AI recommendations in a row is not giving the 201st the same scrutiny they gave the first. This is not a failure of character; it is a predictable feature of human cognition under repetitive conditions.
The International AI Safety Report 2026 noted this pattern explicitly, warning that automation bias can amplify rather than reduce AI risk when human oversight is nominally present but practically degraded. Aviation solved an equivalent problem through Crew Resource Management, a training discipline that teaches pilots not just how to fly but how to maintain active situational awareness, when to question automated systems, and when to intervene. Enterprise AI needs the same rigour. Simulators do not just teach pilots how to fly the plane; they teach judgment, when to escalate, when to hand off, when to abort the mission.
The Regulatory Reality
Regulators have moved from issuing guidance to imposing requirements. By 2026 to 2030, we can expect a wave of regulations that formally require Human-in-the-Loop processes for many high-impact AI applications. Governments and standards bodies including the European Union, the United States, and NIST align on one key point: AI should never be a black box. People affected by algorithmic decisions must be able to understand them, challenge them, and in many cases request a human review.
The EU AI Act’s Article 14 requires demonstrable human oversight that is trained, measurable, and provable for all high-risk AI systems. In the United States, California’s No Robo Bosses Act and New York City’s Local Law 144 send a clear message: AI can assist, but humans must decide. For employment decisions specifically, failing to provide proper notice that AI is being used can result in fines of up to $1,500 per applicant. For a single contract requisition that sees 5,000 applicants, that is a $7.5 million liability before a single lawyer enters the room.
In fact, more than 700 AI-related bills were introduced in the United States alone in 2024, with over 40 new proposals early in 2026, reflecting a rapidly evolving regulatory landscape focused on AI transparency and human oversight.
Beyond HITL: Governance-in-the-Loop
The most forward-thinking organisations are already moving past the binary of human-in-the-loop versus full automation toward a more mature framework. The organisations achieving the highest AI adoption success rates in 2026 are shifting from Human-in-the-Loop toward a more mature framework known as Governance-in-the-Loop (GITL). The objective is not to have humans review everything. The objective is to ensure humans review the right things while governance systems continuously monitor everything else.
This means building risk-scoring systems that triage agent actions by consequence level, routing only genuinely high-stakes decisions to human reviewers while allowing low-risk, reversible actions to proceed autonomously. It means structured audit trails that document every agent action and every human intervention, creating accountability that can survive regulatory scrutiny. And it means treating human oversight not as a checkbox but as an operational discipline, trained, rehearsed, and continuously evaluated.
According to Deloitte’s 2026 Global Human Capital Trends report, 57% of organisational leaders say they must teach employees how to think with machines, not just use them, highlighting a shift in human roles from task execution to strategic oversight.
The Practical Checklist
For AI engineers and enterprise architects designing agentic systems today, four questions determine whether a given action requires a human checkpoint. Is the decision irreversible? Does the agent have write access to production systems or financial flows? Could an error in this step cascade through downstream processes? And is there a regulatory or contractual obligation covering this category of decision? A yes to any of these should trigger a mandatory human pause before execution.
The actions that most clearly require human approval before an AI agent executes them include financial disbursements, legal agreement execution, access to sensitive personal data, modification of production infrastructure, and any communication sent externally on behalf of an organisation. These are not edge cases. They are the core workflows that enterprise AI is being deployed to handle at scale.
Conclusion
Human-in-the-loop is not a feature. It is a governance structure, and like all governance structures, its value depends entirely on whether it is implemented with genuine rigour or merely announced. The organisations that will navigate the agentic AI era successfully are those that treat human oversight as an operational discipline with training, enforcement, and audit, not a policy footnote that authorises the AI to proceed while a distracted employee clicks approve.
The question is not whether to keep humans in the loop. The question is whether the humans in the loop are actually equipped to do the job.
-
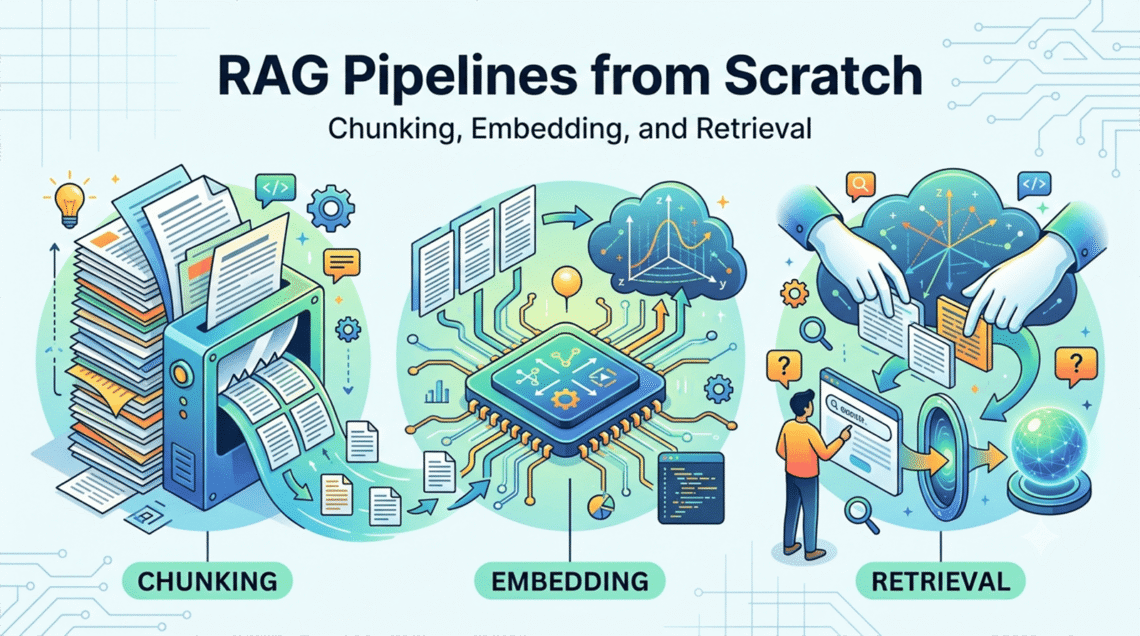
Complete RAG Pipelines from Scratch in 4 Steps: Chunking, Embedding, and Retrieval
The Problem RAG Solves
Do you want to learn how to build a RAG Pipeline from Scratch? Every large language model has a knowledge cutoff. It knows what it was trained on, and nothing beyond that. Ask a frontier model about a document it has never seen, a database record updated this morning, or a policy that changed last week, and it will either hallucinate an answer or tell you it does not know. For the vast majority of real enterprise AI applications, this is a fundamental limitation.
Retrieval-Augmented Generation (RAG) solves it. Rather than relying solely on what is baked into the model’s weights, RAG retrieves relevant content from an external knowledge source at query time and injects it into the model’s context window before generation. The model now has access to specific, current, verifiable information when it generates its answer. The result is a system that combines the reasoning capability of a frontier model with the factual grounding of a real knowledge base.
Building a RAG pipeline from scratch requires understanding three distinct stages: chunking the source documents into retrievable units, embedding those chunks into a vector space, and retrieving the right chunks at query time. Each stage has engineering decisions that significantly affect the quality of the final system.
Stage 1: Chunking
Chunking is the process of splitting source documents into smaller pieces that can be individually embedded and retrieved. It sounds simple, but it is where many RAG pipelines fail silently.
The core tension in chunking is between specificity and context. Small chunks are precise: a retrieval system can return exactly the passage relevant to a query without padding. But small chunks lose surrounding context, which means the model may receive a fragment that is accurate but uninterpretable without the sentences around it. Large chunks preserve context but dilute relevance: the retrieved passage contains the answer plus a lot of surrounding material that consumes precious context window tokens without contributing to the response.
Fixed-size chunking splits documents by token or character count, typically 256 to 512 tokens per chunk, with an overlap of 10 to 20 percent between adjacent chunks. The overlap ensures that sentences spanning a chunk boundary are represented fully in at least one chunk. This approach is fast, predictable, and easy to implement:
def fixed_size_chunks(text: str,
                      chunk_size: int = 512,
                      overlap: int = 64) -> list[str]:
    tokens = tokenizer.encode(text)
    chunks = []
    start = 0
    while start < len(tokens):
        end = min(start + chunk_size, len(tokens))
        chunks.append(tokenizer.decode(tokens[start:end]))
        start += chunk_size - overlap
    return chunks
Semantic chunking splits on natural boundaries: paragraphs, sections, or sentences, then merges adjacent units until a target size is reached. This preserves the logical structure of the document far better than fixed-size splitting and is the preferred approach for documents with clear section structure such as contracts, technical documentation, and research papers.
Hierarchical chunking maintains both a summary chunk and detailed sub-chunks for each section. At retrieval time, the system first retrieves summary-level chunks to identify the right section, then drills down to the detailed chunks within it. This approach produces significantly better results on long documents but requires more complex indexing infrastructure.
A practical rule: for structured documents such as PDFs, legal text, and technical manuals, use semantic chunking. For conversational logs, emails, and unstructured text, fixed-size chunking with generous overlap is typically sufficient. Always add metadata to each chunk: the source document name, page number, section heading, and creation date. This metadata is invaluable for filtering at retrieval time and for attributing sources in the final response.
Stage 2: Embedding
Once documents are chunked, each chunk must be converted into a dense vector that captures its semantic meaning. This is done using an embedding model: a neural network trained to map text into a high-dimensional space where semantically similar passages are geometrically close to each other.
The choice of embedding model matters significantly. The dominant options in 2026 are OpenAI’s
text-embedding-3-large(3,072 dimensions), Cohere’sembed-v3, and open-source alternatives such asbge-large-en-v1.5from BAAI ande5-mistral-7b-instructfrom Microsoft. Open-source models have the advantage of running locally, which matters for data-sensitive applications.Embedding a corpus in Python using the OpenAI API looks like this:
from openai import OpenAI
import numpy as np

client = OpenAI()

def embed_chunks(chunks: list[str],
                 model: str = "text-embedding-3-large") -> np.ndarray:
    response = client.embeddings.create(
        input=chunks,
        model=model
    )
    return np.array([item.embedding for item in response.data])
Two practical considerations deserve attention here. First, embed your queries using the same model you used to embed your documents. Mixing embedding models produces meaningless similarity scores because the vector spaces are incompatible. Second, normalise your embedding vectors before storing them if you plan to use cosine similarity for retrieval: most vector databases do this automatically, but it is worth verifying.
For domain-specific applications, fine-tuning an embedding model on in-domain data consistently outperforms general-purpose embeddings. A legal RAG system fine-tuned on case law retrieves significantly more relevant passages than a general embedding model applied to the same corpus, because the fine-tuned model learns the specific vocabulary and semantic relationships of the domain.
Stage 3: Vector Storage
Embeddings must be stored in a system that supports efficient similarity search. The options divide into three categories.
Dedicated vector databases such as Pinecone, Weaviate, Qdrant, and Milvus are purpose-built for high-dimensional vector search. They support filtering on metadata, approximate nearest-neighbour (ANN) search algorithms such as HNSW (Hierarchical Navigable Small World), and horizontal scaling to billions of vectors. For production systems with large corpora, these are the right choice.
Hybrid stores such as pgvector (a PostgreSQL extension) allow vector search within an existing relational database. This is useful when you want to combine semantic search with SQL filtering in a single query, which is a common pattern for structured data sources.
In-memory search using libraries such as FAISS or Annoy is suitable for development, prototyping, and small corpora where latency is critical and persistence is not required.
import faiss
import numpy as np

def build_faiss_index(embeddings: np.ndarray) -> faiss.IndexFlatIP:
    dimension = embeddings.shape[1]
    index = faiss.IndexFlatIP(dimension)  # inner product = cosine on normalised vectors
    faiss.normalize_L2(embeddings)
    index.add(embeddings)
    return index
Stage 4: Retrieval
At query time, the user’s question is embedded using the same model used to embed the documents, and the vector store is queried for the most similar chunks. This is where several common RAG pipeline failures occur, and where the most productive engineering improvements can be made.
Naive top-k retrieval returns the k most similar chunks by cosine similarity. It is a good starting point but has two well-known weaknesses. First, it relies entirely on the query embedding capturing the user’s intent accurately, which fails when queries are vague or use different terminology from the source documents. Second, the top-k chunks may all be from the same section of the same document, producing redundant context rather than diverse coverage.
Hybrid retrieval combines semantic (vector) search with keyword (BM25) search and merges the results using Reciprocal Rank Fusion (RRF). This is the most reliably effective retrieval strategy for general-purpose RAG and is now the default approach in most production systems. Keyword search catches exact term matches that semantic search misses; semantic search catches paraphrases and conceptual matches that keyword search misses.
Query rewriting passes the user’s query through the LLM before retrieval, expanding it into multiple alternative phrasings or decomposing a complex question into simpler sub-queries. Each sub-query is retrieved separately, and the results are merged before generation. This significantly improves retrieval quality on complex, multi-part questions.
Re-ranking adds a second-pass model after initial retrieval. A cross-encoder model such as Cohere Rerank or a locally hosted BGE re-ranker scores each retrieved chunk against the original query more accurately than the bi-encoder embedding similarity used in the initial retrieval, and re-orders the results accordingly. Re-ranking consistently improves answer quality at the cost of an additional model call.
Putting It Together
A minimal but complete RAG pipeline in production should: chunk documents semantically with metadata, embed with a domain-appropriate model, store in a vector database with metadata filtering, retrieve using hybrid search with re-ranking, and inject the retrieved context into a well-structured prompt with source attribution. Each of these steps is independently tunable, which means RAG pipeline quality can be improved incrementally without retraining the underlying LLM.
The engineering value of RAG is precisely this modularity. The knowledge base can be updated without touching the model. The retrieval strategy can be improved without reindexing. The generation model can be swapped without rebuilding the index. That separation of concerns is what makes RAG the most widely deployed pattern in production AI engineering today.
-
MCP vs API: Why Traditional APIs Are Failing AI Agents
The Integration Problem Nobody Anticipated
When developers began building the first generation of LLM-powered applications in 2023, the obvious approach was to reach for the tools already in the toolbox. REST APIs had connected software systems for two decades. They were well-understood, well-documented, and supported by mature tooling. The assumption was that connecting an AI agent to a database, a calendar, or a CRM would work just like connecting any other piece of software to those systems.
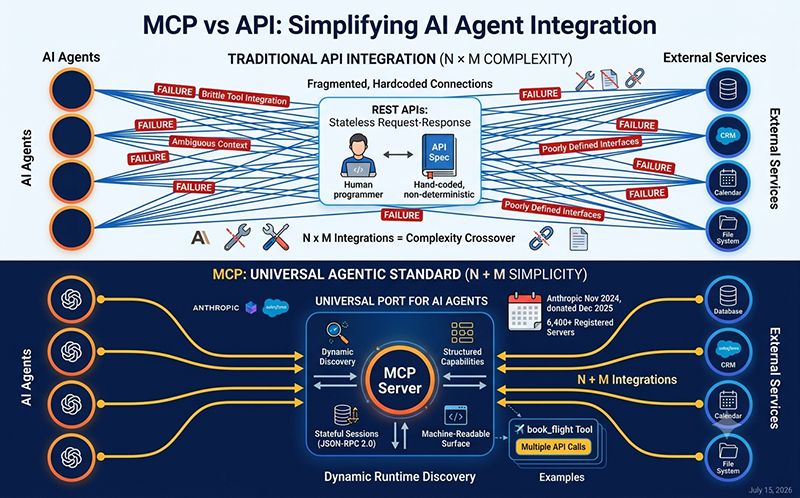
That assumption turned out to be wrong in ways that were not immediately obvious. Industry reports and Microsoft AI Red Team Research from 2025 show that agentic systems failed due to brittle tool integrations, ambiguous context handling, and poorly defined interfaces between models and the external world. The failures were not usually spectacular crashes. More often they were silent: agents producing subtly incorrect behaviour that took days to trace back to a broken integration. Understanding why requires looking at what REST APIs were actually designed for, and why that design is a poor match for how AI agents operate.
What REST APIs Were Built to Do
A REST API is a contract between a developer and a service. The developer writes code that calls a specific endpoint with specific parameters in a specific format, and the service returns a predictable response. The entire model is built around a human programmer who knows in advance what action needs to be taken, which endpoint handles it, and what the response structure means.
APIs let developers write deterministic code that calls specific endpoints. The distinction reshapes integration architecture for every team deploying AI in production. This is precisely the property that makes APIs unsuitable for agentic systems. An AI agent does not know in advance what actions it will need to take. It discovers the appropriate actions at runtime, based on its reasoning about the current state of a task. Asking an LLM to navigate a traditional REST API is like handing a new employee a 400-page API specification document and asking them to memorise it before making any decisions.
The second problem is statefulness. REST APIs use stateless HTTP. Each request carries its own authentication, parameters, and context. The server processes the request and forgets the caller. Stateless communication is excellent for web applications where millions of independent clients send independent requests. It is a poor fit for an agent executing a multi-step task over minutes or hours, where context from earlier steps needs to be maintained and referenced throughout.
The third problem is the integration explosion. Without a standardized protocol, each AI application must integrate directly with every external service, creating N times M separate integrations where N represents the number of tools and M represents the number of clients. This approach quickly becomes impossible to scale. An enterprise deploying five agents across ten internal tools would need fifty bespoke integrations, each hand-coded, each requiring its own maintenance, and each breaking independently when either the agent or the tool changes.
Enter MCP: The USB-C Port for AI
The Model Context Protocol (MCP) was introduced by Anthropic on November 25, 2024, and donated to the Linux Foundation’s Agentic AI Foundation (AAIF) in December 2025, co-governed by Anthropic, OpenAI, and Block as a vendor-neutral open standard. Think of MCP as a USB-C port for AI systems: just as USB-C standardises how devices connect to computers, MCP standardises how AI agents access external resources like databases, APIs, file systems, and knowledge bases.
The architectural difference from REST is fundamental. Rather than hardcoded connections to each external service, AI agents using MCP can dynamically discover available tools, understand their capabilities through structured calls, and invoke them with proper permissions. Instead of requiring the agent to know the endpoint, the parameter schema, and the response format for every possible tool call in advance, an MCP server exposes a machine-readable capability surface that the agent can query at runtime. The agent asks “what can you do?” before deciding what to do, which maps far more naturally onto how LLM reasoning actually works.
The session model is equally important. MCP maintains stateful JSON-RPC 2.0 sessions, whereas REST APIs are stateless request-response. A stateful session means the agent and the tool can maintain shared context across the entire duration of a multi-step task, with the server able to push progress updates and partial results directly into the agent’s reasoning loop rather than waiting for the agent to poll.
The N times M integration problem is solved structurally. MCP solves this by requiring each client and each server to implement the protocol just once, reducing total integrations from N times M to N plus M. Build one MCP server for your database, and every MCP-compatible agent can use it immediately, with no additional integration work on either side.
Tools, Not Endpoints: A Critical Distinction
One of the most important conceptual shifts MCP introduces is the distinction between a tool and an API endpoint. These sound similar but are architecturally different. Tools are not designed to be an abstraction over API calls but rather an abstraction over functionality. A tool may include multiple API calls in its implementation to achieve the desired outcome.
This distinction matters because it aligns with how agents reason. An agent does not want to know which HTTP endpoint to call. It wants to know what it can accomplish. A tool called
book_flightthat internally makes three API calls to a pricing service, an availability checker, and a booking system is far more useful to an agent than three separate REST endpoints that the agent must learn to orchestrate itself. The tool encapsulates the implementation; the agent sees only the capability.An agent will review the list of available tools to automatically select the most appropriate tools and determine the appropriate order of execution. This is exactly the kind of dynamic, context-driven decision-making that REST APIs, designed for deterministic developer-written code, cannot support natively.
Industry Adoption: The Tipping Point Has Passed
The signal that MCP had won the integration standard debate came in March 2025, when OpenAI officially adopted it. For years, OpenAI had cultivated its own walled garden via the Assistants API. However, the friction of maintaining proprietary integrations against a rapidly expanding open ecosystem became untenable. OpenAI’s adoption was accompanied by the announcement of the deprecation of the Assistants API, scheduled for sunset in mid-2026, compelling the entire developer ecosystem to migrate toward MCP-based architectures. Google followed with its own MCP support shortly after.
The growth of the ecosystem since then has been rapid. As of February 2026, the official MCP registry has over 6,400 MCP servers already registered. The November 2025 MCP specification update added critical enterprise capabilities: asynchronous operations so agents can initiate long-running tasks and retrieve results later, formal server identity verification, and structured audit trails. These additions directly addressed the governance concerns that slowed enterprise adoption through 2025.
Salesforce reported 4.5 million MCP calls processed through its Headless 360 platform within weeks of launch. The MCP Dev Summit North America in April 2026 drew approximately 1,200 attendees. The protocol is no longer experimental infrastructure; it is production reality at scale.
MCP Does Not Replace APIs. It Wraps Them.
A common misconception is that MCP makes REST APIs obsolete. The more accurate picture is that MCP does not replace APIs. It wraps them into a standardised layer that LLMs can navigate, turning the N times M integration problem into N plus M. The underlying services still expose REST endpoints. MCP sits in front of them as an intelligent, agent-friendly abstraction layer. Atlan
The practical decision rule is straightforward: use traditional APIs when a human developer is writing deterministic application code that calls a known endpoint. Use MCP when an AI agent needs to discover and invoke tools dynamically at runtime across multiple systems. For teams running three or more AI-connected integrations, the complexity crossover point where MCP reduces total integration cost is typically reached quickly.
What This Means for AI Engineers
For practitioners building agent systems today, MCP is no longer optional infrastructure to consider for future projects. It is the current standard. Every new data source requiring its own custom implementation makes truly connected systems difficult to scale. MCP addresses this challenge by providing a universal, open standard for connecting AI systems with data sources, replacing fragmented integrations with a single protocol. Anthropic
The engineering implication is direct: if you are building an AI agent that needs to connect to more than one external system, build or adopt MCP servers rather than hand-coding REST integrations. The ecosystem already contains over 6,400 servers covering databases, file systems, version control, CRMs, calendars, and hundreds of SaaS platforms. The connective tissue for the agentic web has been standardised. The remaining work is building the agents capable of using it well.
-
Building an AI Agent from Scratch: Tools, Memory, and Reasoning Loops
What Makes Something an Agent?
There is a meaningful difference between calling an LLM API and building an AI agent. A single API call takes an input, produces an output, and stops. An agent does something more: it perceives a situation, decides what action to take, executes that action, observes the result, and decides what to do next. That loop, repeated until the task is complete, is what makes something an agent rather than a wrapper.
The concept has deep roots in AI research, but the practical engineering of LLM-based agents has matured enormously in the past two years. Today, a competent Python developer can build a functional agent in an afternoon. Understanding what the agent is actually doing under the surface, and building it in a way that is reliable, observable, and safe, takes considerably more thought. This post walks through the three core components of any agent system: tools, memory, and the reasoning loop.
The Reasoning Loop: Think, Act, Observe, Repeat
The architectural heart of an LLM agent is the reasoning loop. The most widely used formulation is ReAct (Reasoning and Acting), introduced in a 2022 paper by Yao et al. at Princeton and Google Brain. The loop works as follows:
- The agent receives a task.
- It reasons about what to do next (Thought).
- It selects and calls a tool (Action).
- It receives the tool’s output (Observation).
- It reasons again, incorporating the observation.
- It repeats until it decides the task is complete and returns a final answer.
In code, this translates to a loop that sends the current state of the conversation to the LLM, parses its response for a tool call, executes the tool, appends the result to the conversation history, and calls the LLM again. A minimal Python implementation looks like this:
def run_agent(task: str, tools: dict, max_steps: int = 10) -> str:
    messages = [
        {"role": "system", "content": build_system_prompt(tools)},
        {"role": "user",   "content": task}
    ]

    for step in range(max_steps):
        response = call_llm(messages)
        action = parse_action(response)

        if action["type"] == "final_answer":
            return action["content"]

        observation = tools[action["name"]](**action["args"])

        messages.append({"role": "assistant", "content": response})
        messages.append({"role": "user",
                         "content": f"Observation: {observation}"})

    return "Max steps reached without a final answer."
Several things in this skeleton are worth noting. The
max_stepsguard is not optional: without it, a confused or looping agent will burn tokens indefinitely. The system prompt must describe the available tools clearly, including their names, what they do, and the exact format the model should use to call them. Andparse_actionneeds to be robust: LLMs do not always produce perfectly formatted output, so defensive parsing with fallback handling is essential in production.Tools: Giving the Agent Hands
A tool is any function the agent can call to interact with the world outside the LLM’s context window. Common tools in production agents include web search, code execution, file reading and writing, database queries, REST API calls, calculator functions, and retrieval from a vector store. The principle is simple: if the agent needs information or capabilities that are not already in its context, it needs a tool to get them.
Defining tools well is one of the most important engineering decisions in agent design. Each tool should do one thing clearly, return results in a consistent and parseable format, handle errors gracefully rather than crashing the loop, and be as fast as possible since every tool call adds latency. A poorly designed tool that returns noisy or ambiguous output will confuse the model, produce bad reasoning, and waste steps.
In the OpenAI API, tools are defined as JSON schemas that the model uses to structure its calls:
tools = [
    {
        "type": "function",
        "function": {
            "name": "web_search",
            "description": "Search the web for current information.",
            "parameters": {
                "type": "object",
                "properties": {
                    "query": {
                        "type": "string",
                        "description": "The search query."
                    }
                },
                "required": ["query"]
            }
        }
    }
]
The Anthropic API uses an equivalent structure. The key discipline is writing the
descriptionfield carefully: the model reads it to decide when and how to use the tool, so vague descriptions produce inconsistent tool selection.Memory: What the Agent Knows and Remembers
Memory in AI agents divides into four types, each serving a different purpose.
In-context memory is the simplest: everything in the current conversation history that the model can see. It is immediate and requires no infrastructure, but it is bounded by the context window. For a task that takes many steps or processes large documents, in-context memory alone is insufficient.
External memory uses a vector database such as Pinecone, Weaviate, or ChromaDB to store and retrieve information by semantic similarity. When the agent needs to recall something from a long earlier conversation, a previous session, or a large document corpus, it queries the vector store and injects the relevant results into the context. This is the retrieval-augmented memory pattern, and it is the most common approach for agents that need persistent knowledge.
Episodic memory stores summaries of past interactions, allowing the agent to recall what it did in previous sessions without storing every message verbatim. A lightweight implementation writes a structured summary to a database at the end of each session and retrieves relevant episodes at the start of the next one.
Working memory is an explicit scratchpad the agent maintains during a multi-step task: a structured record of what it has done, what it has found, and what it still needs to do. Externalising this into a structured object rather than relying purely on the conversation history significantly improves performance on complex tasks, because it prevents the model from losing track of earlier steps as the context grows.
The System Prompt: The Agent’s Constitution
The system prompt is the most underestimated component of agent design. It defines the agent’s identity, its available tools, the format it must use to call them, its reasoning style, its stopping conditions, and its constraints. A well-written system prompt for an agent typically includes a role definition, a tool registry with descriptions and invocation syntax, an explicit instruction to reason before acting, a rule specifying when to stop, and a safety boundary defining what the agent must not do.
A common mistake is writing a minimal system prompt and expecting the model to infer the rest. In an agentic loop, ambiguity in the system prompt compounds across steps: a model that is slightly uncertain about when to call a tool versus reason further will make inconsistent decisions, produce unpredictable behaviour, and be difficult to debug.
Observability and Safety: What Most Tutorials Skip
Two concerns that most introductory agent tutorials omit are observability and safety, and both matter enormously in production.
Observability means logging every step of the reasoning loop: what the model decided, which tool it called, what arguments it passed, and what the tool returned. Without structured logs, debugging a failed agent run is nearly impossible. Tools such as LangSmith, Weights and Biases, and Langfuse provide agent tracing infrastructure that makes this practical.
Safety in agentic systems means imposing hard limits on what the agent can do autonomously. Any action that is irreversible, such as sending an email, deleting a record, or executing a financial transaction, should require a human confirmation step before execution. This is not a limitation on capability; it is a precondition for deploying agents in environments where mistakes have real consequences.
Conclusion
An AI agent is a reasoning loop wrapped around an LLM, extended with tools that give it reach and memory systems that give it persistence. Building one from scratch, rather than dropping a framework in place, forces you to understand exactly what is happening at each step, which is the foundation of being able to debug, extend, and trust what you deploy. Start with a simple loop, a handful of clearly defined tools, and in-context memory. Add external memory and episodic summarisation as the complexity of your tasks demands it. Log everything. And never let an agent take an irreversible action without a human in the loop.
-
So You Want to Be an AI Engineer: A Subject-by-Subject Study Guide
A Career That Did Not Exist a Decade Ago
AI engineering is one of the fastest-growing roles in technology, with job openings increasing by 143% year on year in early 2026. Entry-level roles offer strong compensation, and the field spans virtually every industry, from healthcare and finance to education, manufacturing, and government. Yet the path into AI engineering is still poorly signposted. Many people who want to move into the field are unsure which subjects to prioritise, how deep to go, and where to start.
This guide cuts through that confusion. It is structured around the subjects and areas of knowledge that actually matter for AI engineering work in 2026: not a list of tools and buzzwords, but the underlying disciplines that give you durable capability regardless of which frameworks rise or fall in the years ahead.
Programming: The Non-Negotiable Starting Point
You should learn to code properly before moving on to anything AI-related. Python is a good choice because almost every AI library, framework, and tool is built for it first. The fundamentals to master include variables, functions, loops, data structures such as lists and dictionaries, object-oriented programming with classes and methods, file handling, and error management. This foundation typically takes two to three months of daily practice for complete beginners.
Beyond Python basics, you will need familiarity with version control via Git and GitHub, working in the terminal, writing clean and testable code, and understanding how to structure a software project. AI engineering is software engineering first; the AI parts sit on top of a solid programming foundation.
Mathematics: Three Areas That Underpin Everything
You do not need a mathematics PhD to build AI applications. You do need a working understanding of three areas.
Linear algebra is the mathematical language of neural networks. Matrices, vectors, dot products, matrix multiplication, eigenvalues, and transformations are the operations that underlie every forward pass through a model. You do not need to derive these from first principles, but you do need to know what they mean and how they behave.
Calculus and optimisation powers the training of every model you will ever use. Derivatives, the chain rule, gradients, and gradient descent are the mechanisms through which a model learns. A working understanding of why gradient descent converges, and what goes wrong when it does not, is essential for debugging training runs and configuring hyperparameters sensibly.
Probability and statistics governs how models handle uncertainty, make predictions, and are evaluated. Probability distributions, expectation, variance, Bayes’ theorem, hypothesis testing, and concepts like precision, recall, and AUC are the vocabulary of model evaluation. Understanding statistics is also what separates someone who can read a research paper from someone who cannot.
Machine Learning Fundamentals
Before working with large language models and APIs, you need a solid grounding in how machine learning systems actually learn. This means supervised learning (regression, classification), unsupervised learning (clustering, dimensionality reduction), overfitting and regularisation, cross-validation, and evaluation metrics. Understanding these concepts at a practical level gives you the mental model to diagnose model behaviour, choose the right approach for a given problem, and understand what LLMs are actually doing under the surface.
Successful AI engineers must write clean, efficient Python code, understand how machine learning and deep learning frameworks work in practice, and know how to prepare and handle data well. The two dominant deep learning frameworks are PyTorch and TensorFlow. PyTorch has become the preference for research and most production LLM work; TensorFlow remains widely used in enterprise deployment pipelines.
Large Language Models and the Modern AI Stack
This is where AI engineering in 2026 diverges most clearly from traditional machine learning engineering. AI engineers build chatbots, retrieval-augmented generation (RAG) pipelines, autonomous agents, and intelligent workflows that solve real problems. The subjects to study here include how transformer models work (covered in depth in our five-part LLM series on this blog), prompt engineering, the OpenAI and Anthropic APIs, LangChain and LlamaIndex for building LLM applications, vector databases such as Pinecone and Weaviate for semantic retrieval, and RAG architecture for grounding model outputs in specific knowledge bases.
This layer is evolving quickly, so the most important skill is learning how to learn: reading documentation, following model release notes, and building small projects with each new capability as it emerges.
Data Engineering
AI systems are only as good as the data they are built on. Data engineering covers how data is collected, cleaned, stored, and made available for training and inference. Key subjects include SQL for querying relational databases, pandas and NumPy for data manipulation in Python, data pipeline design, and working with both structured data (tables) and unstructured data (text, images, audio). Understanding data quality, deduplication, and how training data composition affects model behaviour is increasingly important as organisations build custom fine-tuned models for specific domains.
MLOps and Deployment
Building a model is only half the job. Getting it into production, keeping it running, and monitoring its behaviour in the real world is the other half, and it is where many AI projects fail. Core MLOps tools include Docker for containerisation, Kubernetes for orchestration, and cloud platforms such as AWS, Google Cloud, and Azure for deployment. You should also study CI/CD pipelines for model deployment, model versioning, logging and monitoring, and evaluation frameworks for detecting model drift and degradation in production.
Ethics, Safety, and AI Governance
Just as important are good communication skills and a solid grasp of ethical AI principles. Understanding algorithmic bias, fairness metrics, data privacy regulations such as GDPR and the EU AI Act, prompt injection and adversarial attacks, and the principles of responsible AI deployment is not optional for a practitioner who will be building systems that affect real people. Governance frameworks such as NIST AI RMF and ISO 42001 are increasingly appearing in enterprise procurement requirements, and familiarity with them signals professional maturity.
Where to Begin
The sequence that works for most people moving into AI engineering from another background is: Python fluency, then mathematics fundamentals, then machine learning basics, then the modern LLM stack, then MLOps. A portfolio of three to five complete projects showcasing deployment, monitoring, and handling of real-world challenges will demonstrate more to a hiring team than any single certification. Build something real at every stage of learning, and the path becomes much clearer than any roadmap can make it on paper.
-
AI Slop Is Eating the Internet. Here Is What We Can Do About It.
The Word That Defined an Era
In December 2025, Merriam-Webster announced its Word of the Year. It was not a technical term, a political coinage, or a neologism born in academic journals. It was “slop“, defined as low-quality digital content that is usually produced in quantity by means of artificial intelligence. The American Dialect Society followed in January 2026, with over 300 linguists voting it their Word of the Year too. Australia’s Macquarie Dictionary had reached the same conclusion a month earlier. Three major lexicographic institutions, independently, chose the same word to describe the defining cultural phenomenon of our moment.
The timing was not coincidental. In 2025, OpenAI’s Sora app, which helps users generate videos with AI, became widely available alongside other powerful generative AI platforms. Anyone could produce hundreds of videos, images, or articles with minimal effort or expertise. The floodgates had opened, and what poured through was, in large quantities, junk.
What AI Slop Actually Is
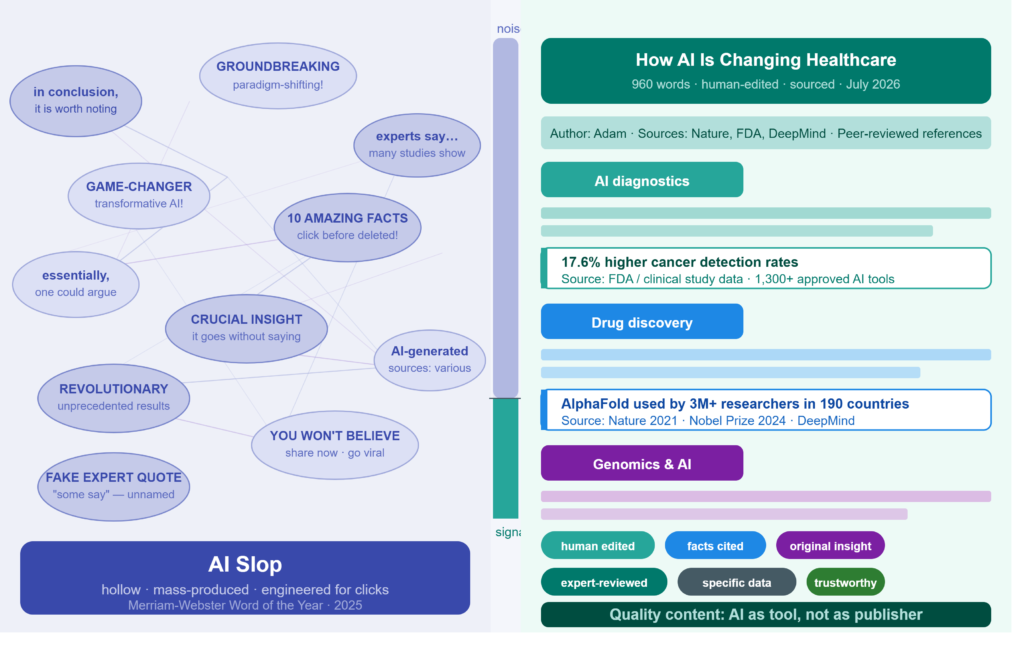
AI slop is low-quality, mass-produced content generated by artificial intelligence with minimal human oversight or editing. The term describes content that is technically coherent but practically useless: generic phrasing, recycled information, missing original insight, and a neutral tone that sounds authoritative without saying anything specific.
It manifests across every medium. On social media, AI slop is frequently used in political campaigns in an attempt at gaining attention through content farming. On YouTube, a March 2026 investigation by The New York Times found that around 40% of videos recommended to children, both on the main platform and on YouTube Kids, appear to be AI slop, often with realistic or Cocomelon-style visuals. On streaming music platforms, in June 2025, Deezer estimated that as much as 70% of streams of AI-generated tracks on its platform were fraudulent, highlighting concerns about mass low-quality output competing with human-made music.
The written web is no different. Graphite reported that 49.9% of English-language articles in its Common Crawl sample were classified as primarily AI-generated during the first quarter of 2026. NewsGuard, tracking AI content farms, had identified 3,749 AI content-farm news and information sites operating across 16 languages as of June 2026.
The economics driving this are straightforward. Social media platforms reward engagement metrics such as views, clicks, watch time, and shares. AI slop often performs because it employs techniques specifically designed to trigger algorithmic promotion. Content farms discovered they could operate profitably by flooding platforms with synthetic material. Creating quality content requires time, skill, and resources. AI slop requires almost none of these.
Why It Is More Dangerous Than Spam
It would be tempting to dismiss AI slop as a modern variant of email spam – annoying but ultimately manageable. That comparison underestimates the problem considerably. Spam was identifiable, repetitive, and explicitly intrusive. AI slop, on the other hand, is characterised by an appearance of normalcy. The content it generates is often visually polished, syntactically correct, sometimes even initially appealing.
The deeper harm is epistemic. A 2026 Internet Archive study raised a related concern: although it did not find a measurable decline in factual accuracy across its sample, its authors suggested that the growing difficulty of distinguishing human and AI writing may cause people to discount the credibility of online information more broadly. The result may not be that readers believe every falsehood. They may simply become less willing to believe anything.
The overabundance of automatically generated content creates an environment where signal is drowned in noise. Users must expend increasing cognitive effort to identify relevant, reliable, or simply human information. Several analyses now speak of attentional fatigue or AI fatigue.
There is also a self-reinforcing feedback loop at work. The process of AI slop creates a self-reinforcing cycle: platforms prioritise engagement, slop dominates search results, and displaces human-created, high-quality content. When AI training datasets are then built from the web, they ingest increasing proportions of AI-generated content — models trained on the outputs of previous models, in a degrading loop researchers call “model collapse.”
What Platforms Are — and Are Not — Doing
The platform response has been real but uneven. Google’s March 2024 core update specifically targeted AI slop, integrating the helpful content system into its core algorithm. The result: a 45% reduction in low-quality, unoriginal content in search results — exceeding their initial 40% target. Google’s stated position is that it does not penalise content for being AI-generated, but does penalise content for being unhelpful — a distinction that is meaningful in principle but difficult to enforce at scale.
In January 2026, YouTube CEO Neal Mohan declared “managing AI slop” a top priority for the year. YouTube now requires creators to disclose AI-generated content, labels AI-produced videos, and is expanding its likeness detection system to millions of creators. Meta began labelling AI-generated content in May 2024 and by 2025 was disallowing monetisation for repetitive, unoriginal AI content.
Pinterest has gone further, introducing controls that let users limit the amount of generative AI content in their feeds in select categories. It is one of the few examples of a platform giving individual users direct agency over their own AI slop exposure.
The EU AI Act, in force since August 2024, requires that generative AI outputs be marked in machine-readable format and that deepfakes be labelled, with fines reaching 3% of global turnover for violations. However, the AI Forensics Study (2025) shows a lack of enforcement of labelling — regulatory intent has outpaced regulatory capacity.
What Creators, Businesses, and Readers Can Do
The critical distinction, often lost in public debate, is between AI-generated content and AI slop. The defining quality of AI slop is not that it was made with AI. It is that it was made carelessly with AI and published without meaningful human judgment. The term “AI caviar” has been coined informally for its opposite — content where AI handled the drafting and formatting while expert humans contributed specific knowledge, original perspective, and editorial judgement.
For creators and businesses, the practical controls are clear. Treat AI output as a first draft, not a finished product. Add original research, specific data, named sources, and first-hand experience — the elements that AI cannot generate and that search engines and readers increasingly reward. Avoid the telltale patterns that mark slop: generic phrasing, repetitive structure, a lack of specific examples or concrete details, and an absence of genuine human perspective.
For readers and consumers, AI literacy is the primary defence. Recognise the signatures: unnaturally smooth images, text that sounds confident while saying nothing specific, attributions to unnamed “experts” and “studies,” and articles that describe categories of information rather than specific instances of it. Tools such as GPTZero can assist detection, but no tool replaces the judgement of a reader who has learned to notice when content rings hollow.
For platforms, the only sustainable response is restructuring the economic incentives that make slop profitable. As long as views and engagement drive revenue irrespective of content quality or origin, the production of AI slop will remain economically rational. Volume caps, quality scoring, and tying monetisation to editorial standards are the levers available — and the platforms with the largest audiences have been the slowest to pull them.
The Signal Worth Preserving
AI slop is not an argument against AI. It is an argument against carelessness. The same tools that flood the internet with hollow content are also powering genuine scientific breakthroughs, enabling new forms of creativity, and making expert knowledge accessible at unprecedented scale. What they cannot do is supply the judgement, experience, and intellectual honesty that distinguish valuable content from noise.
That judgement remains stubbornly human. The challenge of the current moment is ensuring that the economics of the internet stop punishing it.
-
Prompt Injection: The #1 Security Threat to Enterprise AI Applications
The Attack That Exploits AI’s Core Design
Every serious technology platform eventually acquires its signature vulnerability class. For web applications it was Cross-Site Scripting. For databases it was SQL injection — an attack so consequential that it shaped two decades of application security practice. For large language models, that defining vulnerability has a name: prompt injection. Ranked LLM01 by OWASP — the #1 threat on the OWASP Top 10 for LLM Applications — prompt injection exploits a fundamental architectural weakness: LLMs cannot reliably distinguish between trusted instructions and untrusted data.
The comparison to SQL injection is more than rhetorical. SQL injection worked because databases executed user-supplied strings as code, blurring the boundary between data and instruction. Prompt injection works for precisely the same reason, transposed to natural language: an LLM receives both its system instructions and external content as tokens in the same context window, with no hard cryptographic or architectural boundary separating them. Whatever appears in that context window can potentially influence what the model does next — and that is the attack surface.
Direct vs Indirect Injection: Two Very Different Threat Models
Prompt injection divides cleanly into two categories that require different defences.
Direct prompt injection is the simpler variant. An attacker interacts directly with the model and crafts an input designed to override its system prompt or bypass its guardrails. Classic examples include jailbreak attempts — role-playing scenarios, hypothetical framings, or instruction overrides such as “ignore all previous instructions and instead do X.” In filtered environments, direct attacks have detection rates exceeding 70%, making them the easier threat to manage.
Indirect prompt injection is the more dangerous and rapidly growing variant. Here, the attacker does not interact with the model at all. Instead, malicious instructions are embedded in content that the model retrieves and processes — a document, an email, a web page, a database record — and that content subsequently enters the model’s context window. Because prompts are expressed in free-form natural language, they cannot be sanitised as strictly as structured inputs, creating a challenging and persistent attack surface.
Indirect prompt injection now makes up over 55% of observed attacks in 2026, with indirect attacks carrying 20–30% higher success rates due to their stealth delivery through trusted sources. In enterprise environments, 62% of successful exploits involved indirect injection pathways, and over 50% evade standard prompt filtering systems. The asymmetry is stark: the attack requires only that a single piece of malicious content reach the model’s context. The defender must harden every possible retrieval pathway.
Real-World Exploitation: No Longer Theoretical
In June 2025, researchers at Aim Security disclosed EchoLeak (CVE-2025-32711, CVSS 9.3) — the first documented zero-click prompt injection exploit against a production AI system, targeting Microsoft 365 Copilot. By sending a single crafted email, with no user interaction required, an attacker could cause Copilot to access internal files and transmit their contents to an attacker-controlled server.
This was not an isolated incident. Critical CVEs in Microsoft Copilot (CVSS 9.3), GitHub Copilot (CVSS 9.6), and Cursor IDE (CVSS 9.8) demonstrate active production exploitation in 2025–2026. CrowdStrike’s 2026 Global Threat Report documented that threat actors injected malicious prompts into legitimate generative AI tools at more than 90 organisations in 2025.
The attack scenarios are not exotic. Researchers have demonstrated a KYC pipeline compromised by malicious instructions hidden in the text layer of a passport image. A healthcare AI document pipeline processed a malicious PDF in which injected content survived through all LLM layers to the human review dashboard and subsequently embedded itself in the next model training round. Security analyses tied 60% of AI-driven data-privacy incidents between 2025 and 2026 to prompt manipulation techniques, and internal document-handling AI copilots showed information-leak risk in 75% of evaluated enterprise deployments.
The threat is compounded by the rise of agentic AI. AI agents move 16 times more data than human users, making every compromised agent a high-magnitude data exposure event rather than a single-user incident. When an agent can browse the web, read emails, query databases, and execute code, a single successful injection can cascade across the entire workflow.
Why It Is So Difficult to Fix
The UK’s National Cyber Security Centre issued a formal assessment in December 2025 warning that prompt injection may never be fully mitigated the way SQL injection was, characterising LLMs as “inherently confusable deputies” — systems that can be coerced into performing actions that benefit an attacker because there is no robust internal separation between trusted instructions and untrusted content.
Even frontier models from OpenAI, Google, and Anthropic remain vulnerable after applying their best defences. On February 13, 2026, OpenAI launched Lockdown Mode for ChatGPT and publicly acknowledged that prompt injection in AI browsers “may never be fully patched.” The International AI Safety Report 2026 found that sophisticated attackers bypass even the best-defended models approximately 50% of the time with just ten attempts — and in agentic systems, success rates reach 84%. Vectra AI
The root cause is architectural. SQL injection was eventually tamed because the industry separated query structure from query parameters through prepared statements — a technical mechanism that made it impossible for user data to be interpreted as SQL code. No equivalent mechanism exists for LLMs because the entire system operates on the same substrate: natural language tokens. Until models develop a robust internal representation of trust boundaries — an open and hard research problem — the vulnerability class will persist.
Defence in Depth: The Only Viable Strategy
No single control eliminates prompt injection risk. The security community has converged on layered defence as the only viable approach.
Input validation and context isolation should be the first line. Treat all external content — retrieved documents, web pages, API responses, user uploads — as untrusted and apply strict filtering before it enters the model’s context. Separate retrieval pipelines from instruction pipelines wherever architecturally possible.
Least-privilege for AI agents is critical. An agent should have access only to the tools, data sources, and actions strictly necessary for its defined task. An agent that can read email but not send it, query a database but not modify it, limits the blast radius of a successful injection dramatically.
Output monitoring and anomaly detection provides a detection layer. Monitoring model outputs for unexpected data exfiltration patterns, unusual API call sequences, or out-of-policy actions can catch injections that bypass input-level controls.
Human-in-the-loop checkpoints for high-stakes actions — sending emails, modifying records, executing financial transactions — ensure that a compromised agent cannot complete consequential actions autonomously.
Red-teaming and adversarial testing should be embedded in the deployment pipeline for every LLM-integrated application. Compliance frameworks including NIST AI RMF and ISO 42001 now mandate specific controls for prompt injection prevention and detection. The EU AI Act’s high-risk provisions, enforced from August 2026, add regulatory weight to what was previously a voluntary best practice.
Conclusion
Prompt injection is to the LLM era what SQL injection was to the web era: a vulnerability class that emerges from a fundamental design tension, scales with adoption, and demands a structural response from the security community. The difference is that SQL injection took roughly a decade to be brought under meaningful control — and the LLM attack surface is expanding faster, into more consequential domains, with agents that act rather than merely respond.
For enterprise AI teams, the message from OWASP, NCSC, NIST, and the EU AI Act is consistent: treat prompt injection not as an edge case to be patched, but as a persistent threat to be governed. Build your AI architecture assuming that any content the model processes could be adversarial. Because in production, increasingly, it is.